Microsoft patents method to auto-generate training data for matching models
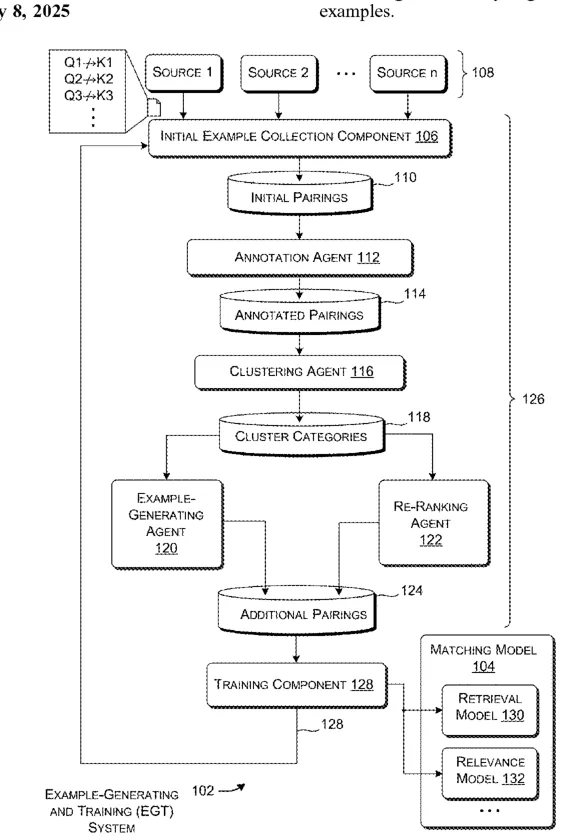
Microsoft describes a multi-step process for creating training data to improve how software matches user queries with specific items. The system uses automated agents to label errors, group them into categories, and generate new examples of mismatches to help the model learn.
In the filing’s own words
A technique for training a machine-trained matching model (“matching model”) includes a multi-stage process for generating training examples. The technique includes: receiving initial pairs of queries and identified items (e.g., identified keywords); annotating the initial pairs with annotations using an annotation computer-implemented agent, to provide annotated pairs; clustering the annotated pairs into categories using a clustering computer-implemented agent; generating additional examples of query-item mismatches based on the categories, using an example-generating computer-implemented agent; and training the matching model based on at least the additional examples. The technique provides a time-efficient and resource-efficient way of assembling a sufficiently large collection of relevant training examples.
What exactly they claim (claim 1)
1. A method for training a machine-trained matching model, comprising: receiving initial pairs of queries and identified items, a particular initial pair being an example of an error made by a current version of the machine-trained matching model in pairing a particular submitted query with a particular item; annotating the initial pairs with annotations using an annotation computer-implemented agent, to provide annotated pairs, an explanation for the particular initial pair specifying a reason why the particular submitted query fails to match the particular identified item; clustering the annotated pairs into categories using a clustering computer-implemented agent; generating additional examples of query-item mismatches based on the categories, using an example-generating computer-implemented agent; and training the machine-trained matching model based on at least the additional examples, the training including generating loss information, and updating parameters of the machine-trained matching model using back propagation through layers of the machine-trained matching model based on the loss information.
Facts
- Company
- Microsoft (Microsoft Technology Licensing, LLC)
- Official title
- Augmenting a Set of Training Examples for Training a Model
- Publication number
- US20260359712A1
- Application number
- 19201963
- Filed
- May 8, 2025
- Published
- Nov 12, 2026
- Inventors
- 7
- Claims
- 20
Classified under
G06N 20/00 Physics & computingG06F 16/285 Physics & computingG06F 16/953 Physics & computingMore from Microsoft in AI & software
- Microsoft patents method to check AI answers against verified facts Oct 20, 2026
- Microsoft patents AI that presents PowerPoint slides for you Sep 3, 2026
- Microsoft patents method to check if LLM answers are based on real data Sep 10, 2026
- Microsoft patents system to blend multiple AI agents into one chat Oct 1, 2026
- Microsoft patents system that answers questions using your screen history Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.