Microsoft patents method for better feeding code context to AI models
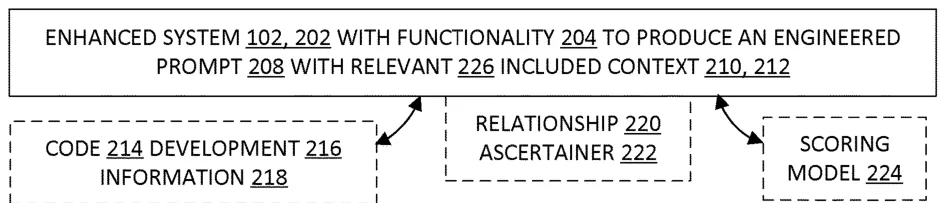
This filing describes a system that helps software developers get better results from AI coding assistants. It works by analyzing specific project data, like code errors or settings, to decide which extra information is most relevant to include in the request sent to the AI.
In the filing’s own words
Some embodiments engineer a prompt for submission to a language model, such as a software development large language model. Some embodiments ascertain a relationship between code development information and potential context. Code development information includes static analysis results, project settings, development tool history or status data, and other software development data which augments training data previously embedded in the language model. Some embodiments compute a prompt inclusion score of the potential context, based on at least the relationship, and use the inclusion score to determine whether to include the potential context in the language model prompt. In some scenarios, an embodiment determines where to place the context in the prompt. Scoring is performed by a formula, statistical scoring model, or machine learning scoring model. Some embodiments reduce context inclusion false positives and false negatives that were based on the use of embedding similarity scores alone.
What exactly they claim (claim 1)
1. A computing system comprising: a processor set; and a memory storing computer-executable instructions that are executable by the processor set to: receive a first language model prompt that requests performance of a task regarding development of source code; select a portion of potential prompt content from a plurality of portions of the potential prompt content based on a determined relevance of the portion of the potential prompt content to code development information, which is associated with the development of the source code, relative to respective determined relevances of other portions of the potential prompt content to the code development information, at least the portion of the potential prompt content or the first language model prompt having an embedding in an embedding space of a language model, the determined relevance being based on a relationship between the portion of the potential prompt content and the code development information; generate a second language model prompt by including the portion of the potential prompt content in the first language model prompt; and cause the language model to perform the task regarding the development of the source code by providing the second language model prompt to the language model.
Facts
- Company
- Microsoft (Microsoft Technology Licensing, LLC)
- Official title
- SOFTWARE DEVELOPMENT LANGUAGE MODEL PROMPT ENGINEERING
- Publication number
- US20260359016A1
- Application number
- 19743475
- Filed
- Jul 15, 2026
- Published
- Nov 12, 2026
- Inventors
- 3
- Claims
- 20
Classified under
G06F 8/33 Physics & computingG06F 8/75 Physics & computingMore from Microsoft in AI & software
- Microsoft patents method to check AI answers against verified facts Oct 20, 2026
- Microsoft patents AI that presents PowerPoint slides for you Sep 3, 2026
- Microsoft patents method to check if LLM answers are based on real data Sep 10, 2026
- Microsoft patents system to blend multiple AI agents into one chat Oct 1, 2026
- Microsoft patents system that answers questions using your screen history Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.