Nvidia patents method for splitting attention math across GPU grids
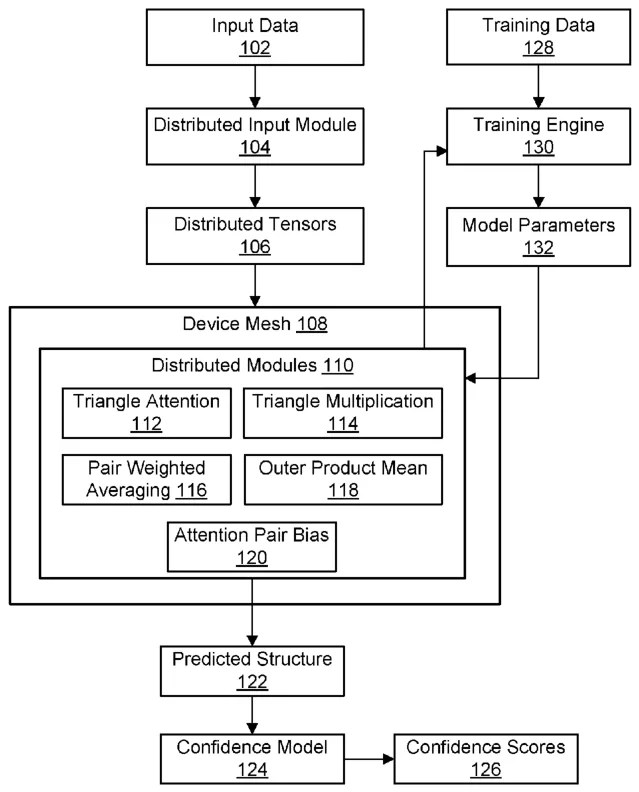
Nvidia describes a way to break down the 'attention' calculations used in machine learning models into smaller chunks. These chunks are moved across a grid of graphics processors in a specific order to help them work together on the same task.
In the filing’s own words
Apparatuses, systems, and techniques to perform distributed attention computations for machine-learning models. In at least one embodiment, a local query block generated from a single-representation tensor and communicated attention data including key blocks, value blocks, and pair-bias blocks derived from a pair-representation tensor are used to compute a local attention contribution and local normalization information, and to update a local normalization state and a local output block corresponding to the local query block.
What exactly they claim (claim 1)
1. One or more processors, comprising: circuitry to: generate, for an attention computation, a local query block; prior to repeated ring-communication steps along a first mesh axis of a two-dimensional GPU mesh, redistribute key blocks, value blocks, and, where used, mask blocks across a second mesh axis of the two-dimensional GPU mesh; during the repeated ring-communication steps along the first mesh axis, receive communicated attention data including key blocks, value blocks, and pair-bias blocks derived from a pair-representation tensor, wherein the pair-bias blocks are passed in coordination with corresponding key blocks and value blocks such that, at each repeated ring-communication step, a received key block, a received value block, and a received pair-bias block correspond to the same query-key comparisons as the local query block; and generate a local output block for the local query block based on local attention contributions computed using the local query block and the communicated attention data.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- DISTRIBUTED ATTENTION PAIR BIAS
- Publication number
- US20260359726A1
- Application number
- 19672630
- Filed
- May 9, 2026
- Published
- Nov 12, 2026
- Inventors
- 8
- Claims
- 20
Classified under
G06N 20/00 Physics & computingMore from Nvidia in Chips & hardware
- Nvidia stacks memory directly on chips to boost data speed Nov 10, 2026
- Nvidia patents method to skip zero data in neural network math Oct 13, 2026
- Nvidia patents hardware to speed up motion blur in ray tracing Oct 13, 2026
- Nvidia patents method to sync data across split processor chips Sep 17, 2026
- Nvidia patents chip math trick to speed up AI calculations Oct 8, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.