Nvidia patents chip method for speeding up specific neural network math
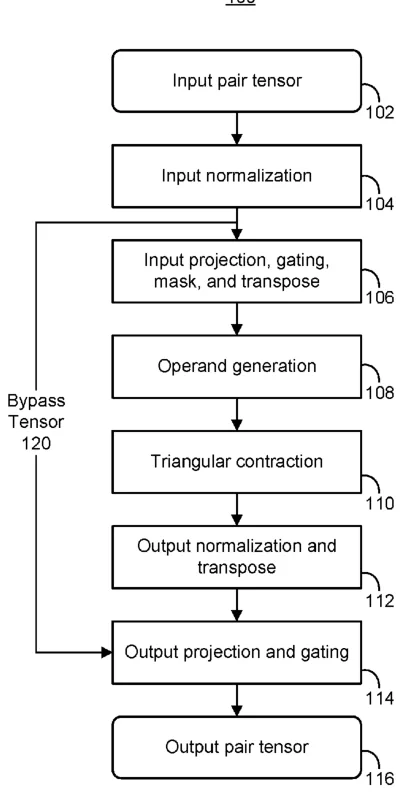
Nvidia describes a way for its specialized processors to handle a specific type of neural network calculation called a triangular multiplicative update. The system reorganizes data in memory to match the chip's structure, allowing it to perform complex matrix math more efficiently without extra steps.
In the filing’s own words
Apparatuses, systems, and techniques are to perform a triangular multiplicative update using a compiler-scheduled processor, such as a Language Processing Unit (LPU). Producer operations of a neural-network graph generate a first tensor and a second tensor from an input tensor and store the tensors in a second ordered memory layout in which a feature-channel axis precedes a first pair-index axis and a second pair-index axis. The storing performs a transpose by writing tensor elements directly to addresses corresponding to the second ordered memory layout. A triangular contraction consumes the first tensor and the second tensor in the second ordered memory layout and computes a triangular multiplicative update tensor in a batched matrix-multiplication form over an intermediate index. Downstream operations may consume the triangular multiplicative update tensor while the tensor remains stored in the second ordered memory layout.
What exactly they claim (claim 1)
1. One or more processors, comprising: circuitry to: receive an input tensor representing features and stored in memory according to a first ordered memory layout, the input tensor including a feature-channel axis, a first pair-index axis, and a second pair-index axis; execute, on a Language Processing Unit (LPU), a triangular multiplicative update graph to generate a first tensor and a second tensor and store the first tensor and the second tensor in memory according to a second ordered memory layout in which the feature-channel axis is a leading axis, wherein the storing performs a transpose that reorders the feature-channel axis relative to the first pair-index axis and the second pair-index axis; and compute, on the LPU, a triangular multiplicative update tensor by performing a tensor contraction between the first tensor and the second tensor that sums over an intermediate index.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- COMPILER-SCHEDULED TRIANGULAR UPDATE NEURAL NETWORK
- Publication number
- US20260359632A1
- Application number
- 19672610
- Filed
- May 9, 2026
- Published
- Nov 12, 2026
- Inventors
- 6
- Claims
- 20
Classified under
G06N 3/08 Physics & computingMore from Nvidia in Chips & hardware
- Nvidia stacks memory directly on chips to boost data speed Nov 10, 2026
- Nvidia patents method to skip zero data in neural network math Oct 13, 2026
- Nvidia patents hardware to speed up motion blur in ray tracing Oct 13, 2026
- Nvidia patents method to sync data across split processor chips Sep 17, 2026
- Nvidia patents chip math trick to speed up AI calculations Oct 8, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.