Nvidia patents method for splitting complex math across chips
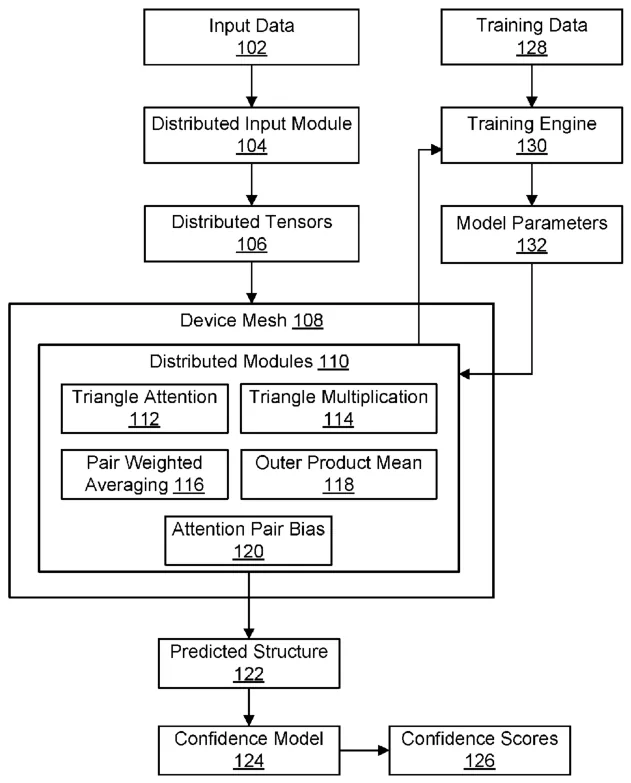
Nvidia describes a technique for performing a specific type of mathematical calculation called an outer-product mean across multiple processors. The system breaks the data into smaller blocks, calculates parts of the result locally, and then combines these pieces with data from other processors to build the final answer.
In the filing’s own words
Apparatuses, systems, and techniques to perform distributed outer-product-mean computations for machine-learning models. In at least one embodiment, local projected blocks generated from a sequence-alignment representation and communicated projected blocks aligned with the local projected blocks are used to compute a local outer-product contribution, and a local pair block is updated based on the local outer-product contribution, a previously generated local pair block, and normalization information associated with aligned sequences.
What exactly they claim (claim 1)
1. One or more processors, comprising: circuitry to: generate local projected blocks of a first projected tensor and a second projected tensor for an outer-product-mean computation from a local block of a sequence-alignment representation; receive communicated projected blocks of one of the first projected tensor and the second projected tensor aligned with local projected blocks of the other of the first projected tensor and the second projected tensor for the outer-product-mean computation; compute, based on the local projected blocks and the communicated projected blocks, a local outer-product contribution for ordered pairs of aligned positions of a local pair block; and generate an updated local pair block for the outer-product-mean computation by combining the local outer-product contribution with an accumulated local pair block and normalization information associated with aligned sequences of an aligned-sequence axis of the sequence-alignment representation, the normalization information comprising count information associated with the aligned sequences contributing to the local pair block.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- DISTRIBUTED OUTER PRODUCT MEAN
- Publication number
- US20260359389A1
- Application number
- 19672629
- Filed
- May 9, 2026
- Published
- Nov 12, 2026
- Inventors
- 8
- Claims
- 20
Classified under
G06F 17/16 Physics & computingMore from Nvidia in Chips & hardware
- Nvidia stacks memory directly on chips to boost data speed Nov 10, 2026
- Nvidia patents method to skip zero data in neural network math Oct 13, 2026
- Nvidia patents hardware to speed up motion blur in ray tracing Oct 13, 2026
- Nvidia patents method to sync data across split processor chips Sep 17, 2026
- Nvidia patents chip math trick to speed up AI calculations Oct 8, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.