Google patents compressed lookup tables for faster machine learning models
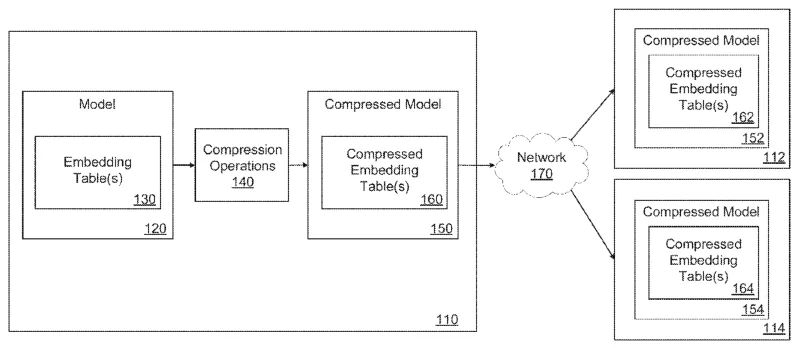
Google describes a method for storing large data tables used in machine learning by compressing each entry individually. This allows the system to find and unpack only the specific piece of data it needs without affecting other entries.
In the filing’s own words
The present disclosure provides systems, methods, and computer program products for providing efficient embedding table storage and lookup in machine-learning models. A computer-implemented method may include obtaining an embedding table comprising a plurality of embeddings respectively associated with a corresponding index of the embedding table, compressing each particular embedding of the embedding table individually allowing each respective embedding of the embedding table to be decompressed independent of any other embedding in the embedding table, packing the embedding table comprising individually compressed embeddings with a machine-learning model, receiving an input to use for locating an embedding in the embedding table, determining a lookup value based on the input to search indexes of the embedding table, locating the embedding based on searching the indexes of the embedding table for the determined lookup value, and decompressing the located embedding independent of any other embedding in the embedding table.
What exactly they claim (claim 1)
1. A computer-implemented method for performing efficient embedding table storage and lookup in machine-learning models, comprising: obtaining, by one or more processors, an embedding table associated with a machine-learning model, the embedding table comprising a plurality of individually compressed allowing each respective embedding to be decompressed independent of any other embedding in the embedding table; receiving, by the one or more processors, an input to use for locating an embedding in the embedding table; determining, by the one or more processors, a lookup value based on the input for searching indexes of the embedding table to locate the embedding; locating, by the one or more processors, the embedding based on searching the indexes of the embedding table for the determined lookup value; and decompressing, by the one or more processors, the embedding independent of any other embedding in the embedding table in view of the locating.
Facts
- Company
- Google (Google LLC)
- Official title
- Efficient Embedding Table Storage and Lookup
- Publication number
- US20260359282A1
- Application number
- 19747881
- Filed
- Jul 20, 2026
- Published
- Nov 12, 2026
- Inventors
- 1
- Claims
- 13
Classified under
G06F 16/2282 Physics & computingG06F 16/215 Physics & computingG06F 16/2255 Physics & computingG06F 16/3347 Physics & computingG06F 30/27 Physics & computingG06N 3/04 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents method for LLMs to self-correct and learn from mistakes Oct 27, 2026
- Google patents search results that mix real clips with AI-made video Nov 10, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.