Nvidia patents math trick to speed up AI training on multiple chips
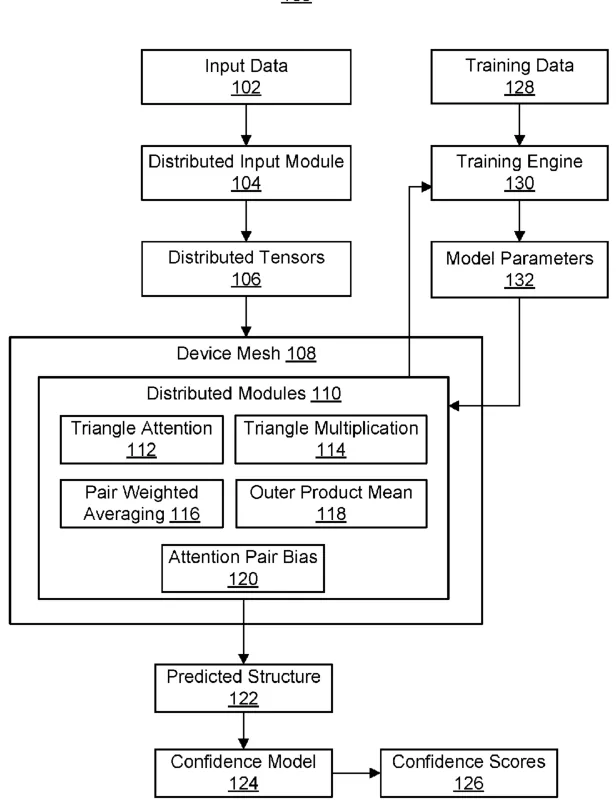
Nvidia has filed a patent for a method to perform large matrix calculations across a grid of graphics processing units. The system breaks down the math into smaller pieces, shares specific data blocks between chips, and combines the results to speed up machine learning tasks.
In the filing’s own words
Apparatuses, systems, and techniques to perform distributed triangle multiplication computations for machine-learning models. In at least one embodiment, a local first tensor block and a local second tensor block are generated from local blocks of input tensors, a redistributed tensor block aligned on a shared index is used to compute a local multiply-and-accumulate contribution, and a local output block is updated based on the local multiply-and-accumulate contribution and a previously generated local output block.
What exactly they claim (claim 1)
1. One or more processors comprising circuitry to: generate, for a triangle multiplication computation, a local first tensor block from a local block of a first input tensor and a local second tensor block from a local block of a second input tensor, wherein the one or more processors are of a GPU in a two-dimensional GPU mesh, and wherein the first input tensor and the second input tensor are pair-derived tensors derived from a pair-representation tensor; receive a redistributed tensor block, the redistributed tensor block being aligned on a shared sequence-position dimension with a local tensor block corresponding to the other input tensor for contraction over the shared sequence-position dimension, wherein the redistributed tensor block corresponds to the first input tensor or the second input tensor according to whether the triangle multiplication computation is an outgoing variant or an incoming variant; compute, based on the redistributed tensor block and the local tensor block, a local multiply-and-accumulate contribution; and generate an updated local output block by accumulating the local multiply-and-accumulate contribution with a previously generated local output block.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- DISTRIBUTED TRIANGLE MULTIPLICATION
- Publication number
- US20260359009A1
- Application number
- 19672625
- Filed
- May 9, 2026
- Published
- Nov 12, 2026
- Inventors
- 8
- Claims
- 20
Classified under
G06F 7/5443 Physics & computingG06F 5/01 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents chip that turns text into video using noise reduction Nov 5, 2026
- Nvidia patents system that translates specific speakers in group conversations Nov 12, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.