Nvidia patents system that translates specific speakers in group conversations
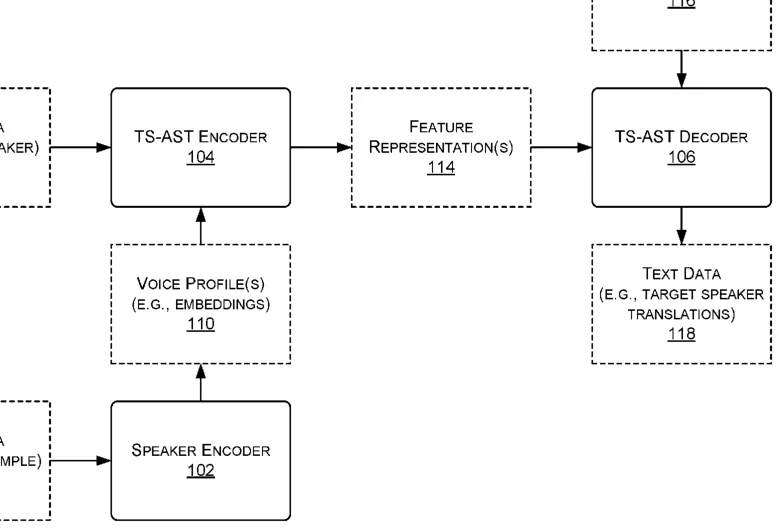
Nvidia describes a single machine learning model that identifies a specific person's voice in a noisy group conversation and translates their words directly into another language. The system uses a short audio sample to create a voice profile, allowing it to ignore other speakers and skip the usual steps of first transcribing the audio and then translating the text.
In the filing’s own words
In various examples, AI-based techniques may be used to translate speech of specific speakers in multi-speaker environments. For example, the systems and methods of the present disclosure may integrate target speaker extraction with automatic speech translation (AST) into a single AST model. Based on this integration, the AST model may be used to extract the speech of a specified speaker from mixed audio and directly translate the speech into text of a target language without intermediate transcription. For instance, the AST model may receive a speech sample for the speaker and use the sample to identify and extract the target speaker’s voice from a dialogue. The AST model may then process the extracted speech and generate a direct translation without requiring separate automatic speech recognition (ASR) and machine translation (MT) stages.
What exactly they claim (claim 1)
1. A method comprising: generating, using one or more first encoders of a machine learning model and based at least on first audio data representing speech of a target speaker, a voice profile associated with the target speaker; determining, using one or more second encoders of the machine learning model and based at least on the voice profile and second audio data representing a multi-speaker dialogue, one or more portions of the multi-speaker dialogue that correspond to the target speaker; and generating, using one or more decoders of the machine learning model, output data representing text or speech corresponding to one or more translations of the one or more portions of the multi-speaker dialogue from a first language into one or more second languages.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- IDENTITY-BASED SPEAKER TARGETING FOR AUTOMATIC SPEECH TRANSLATION SYSTEMS AND APPLICATIONS
- Publication number
- US20260360368A1
- Application number
- 19205716
- Filed
- May 12, 2025
- Published
- Nov 12, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G10L 17/26 Physics & computingG06F 40/58 Physics & computingG10L 15/005 Physics & computingG10L 17/18 Physics & computingG10L 21/0208 Physics & computingG10L 2021/02087 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents chip that turns text into video using noise reduction Nov 5, 2026
- Nvidia patents AI that creates 3D medical scans from text prompts Nov 12, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.