Google patents speech emotion recognition using language models
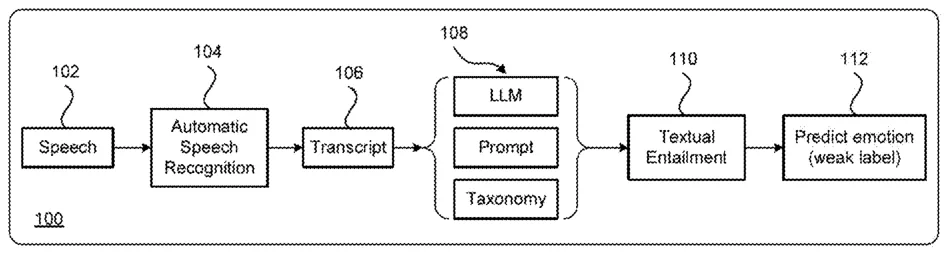
Google describes a method for training speech emotion recognition systems by using large language models to guess emotions from text transcripts. The system creates a list of possible emotions based on the specific app being used and picks the most likely match to label audio data without manual work.
In the filing’s own words
The technology relates to enhancing speech emotion recognition models with methods that enable the use of unlabeled data by inferring weak emotion labels. This is done by pre-trained large language models through weakly-supervised learning. For inferring weak labels constrained to a taxonomy, a textual entailment approach selects an emotion label with the highest entailment score for a speech transcript extracted via automatic speech recognition. The system may employ a method that generates, by one or more processors, a text transcript for a snippet of input speech, and then applies the text transcript to a pre-trained language model. The system can generate, using the pre-trained language model according to an engineered prompt and a predetermined taxonomy, a textual entailment from the text transcript. Based on this, the system may generate, by the one or more processors using the textual entailment, a predicted emotion corresponding to the input speech.
What exactly they claim (claim 1)
1. A method for training a speech emotion recognition (SER) model for use with a specific application or product, comprising: generating, by one or more processors, a text transcript for a snippet of input speech; applying, by the one or more processors, the text transcript to a pre-trained language model; generating, using the pre-trained language model according to an engineered prompt and a particular predetermined taxonomy, a textual entailment from the text transcript, wherein the particular predetermined taxonomy (i) is chosen based on the specific application or product with which the SER model is used and (ii) includes a set of words or phrases corresponding to the specific application or product; and generating, by the one or more processors using the textual entailment, a predicted emotion corresponding to the input speech, wherein the predicted emotion is applied as a weak label to train the SER model on the input speech for weakly-supervised learning of the SER model.
Facts
- Company
- Google (Google LLC)
- Official title
- Language-model supported speech emotion recognition
- Patent number
- US12802713B2
- Application number
- 18235372
- Filed
- Aug 18, 2023
- Granted
- Nov 17, 2026
- Inventors
- 6
- Claims
- 17
Classified under
G10L 25/63 Physics & computingG06F 40/279 Physics & computingG06F 40/30 Physics & computingG10L 15/063 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents method for LLMs to self-correct and learn from mistakes Oct 27, 2026
- Google patents search results that mix real clips with AI-made video Nov 10, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.