Nvidia patents method to align text and speech in AI models
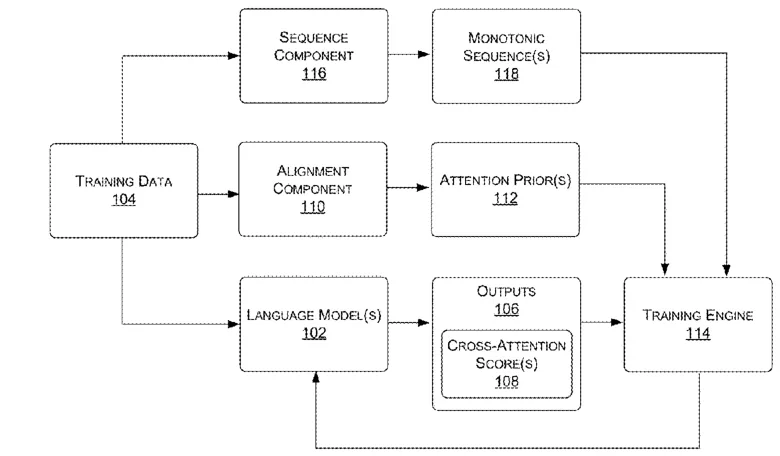
Nvidia describes a training method for language models that improves how text is matched to spoken audio. The system uses specific mathematical rules to ensure the model processes words in order, making the generated speech more consistent and less likely to skip or repeat parts.
In the filing’s own words
In various examples, learning monotonic alignment for language models in AI systems and applications is described herein. Systems and methods are disclosed that train one or more language models—such as LLMs or VLMs—using one or more techniques that improve the ability of the language model(s) to align inputs (e.g., text tokens) with outputs (e.g., speech tokens). For instance, to learn a stricter alignment and improve robustness of the language model(s), the training may encourage monotonic cross-attention scores using one or more attention priors and/or using one or more connectionist temporal classification (CTC) losses when updating the language model(s). For instance, the attention prior(s) may initialize the cross-attention scores to a monotonic heuristic while the CTC loss(es) may ensure the learned alignment attends over one or more text tokens (e.g., all text tokens) sequentially.
What exactly they claim (claim 1)
1. A method comprising: determining, based at least on one or more language models processing text data representative of text, one or more cross-attention scores associated with one or more layers of a decoder of the one or more language models; determining, based at least on one or more text tokens associated with the text data and one or more time durations associated with aligning one or more speech tokens output by the decoder with the one or more text tokens, one or more attention priors associated with the text data; and updating one or more parameters associated with the one or more language models based at least on the one or more cross-attention scores and the one or more attention priors.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- Speech synthesis
- Patent number
- US12802679B2
- Application number
- 18649000
- Filed
- Apr 29, 2024
- Granted
- Nov 17, 2026
- Inventors
- 6
- Claims
- 20
Classified under
G10L 13/02 Physics & computingG10L 25/30 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents chip that turns text into video using noise reduction Nov 5, 2026
- Nvidia patents system that translates specific speakers in group conversations Nov 12, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.