Disney patents AI that lets actors speak in a character's voice
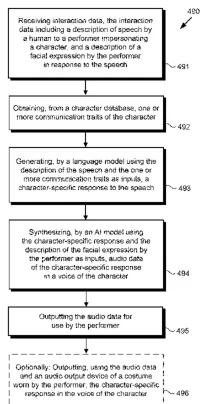
This system uses a large language model to generate a character's reply based on a visitor's speech and the character's known traits. An AI model then turns that text into audio that matches the character's voice, which is played through a wearable device worn by the actor.
In the filing’s own words
A system includes a hardware processor and a memory storing software code, a character database, a language model and an artificial intelligence (AI) model trained to emulate speech by a character. The software code is executed to receive interaction data including a description of speech by a human to a performer impersonating the character and a description of a facial expression by the performer in response, obtain, from the character database, one or more communication trait(s) of the character, and generate, by the language model using the description of the speech and the communication trait(s) as inputs, a character-specific response to the speech. The software code is further executed to synthesize, by the AI model using the character-specific response and the description of the facial expression as inputs, audio data of the character-specific response in a voice of the character, and output the audio data for use by the performer.
What exactly they claim (claim 1)
1. A system comprising: a computing platform including a hardware processor and a system memory, the system memory storing a software code, a character database, a large language model, and an artificial intelligence (AI) model trained to emulate speech by a character; wherein the hardware processor is configured to execute the software code to: receive interaction data including (i) a description of a speech by a first human to a second human who is not the first human, the second human impersonating the character while wearing a performance accessory, and (ii) a description of a facial expression by the second human in response to the speech; obtain, from the character database, one or more communication traits of the character including a prosody of the character; generate, by the large language model using the description of the speech and the one or more communication traits as inputs, in real-time with respect to the speech by the first human, a character-specific response to the speech; and synthesize, by the AI model using the character-specific response and the description of the facial expression by the second human as inputs, audio data of the character-specific response in a voice of the character; and the performance accessory configured to: receive the synthesized audio data; and output, using the synthesized audio data and an audio output device of the performance accessory, the character-specific response in the voice of the character.
Facts
- Company
- Disney (Disney Enterprises, Inc.)
- Official title
- Artificial intelligence based character-specific speech generation
- Patent number
- US12784732B2
- Application number
- 18669410
- Filed
- May 20, 2024
- Granted
- Nov 3, 2026
- Inventors
- 2
- Claims
- 19
Classified under
G10L 13/047 Physics & computingG10L 13/027 Physics & computingG10L 15/18 Physics & computingG10L 15/183 Physics & computingMore from Disney in AI & software
- Disney patents AI character that creates art from your shared memories Sep 8, 2026
- Disney patents video compression using generative models to cut file sizes Sep 3, 2026
- Disney patents AI characters that create art from shared memories Oct 22, 2026
- Disney patents tech to sync translated speech with body gestures Sep 17, 2026
- Disney patents AI characters that pause and react when you interrupt them Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.