OpenAI patents chip design that keeps AI weights in place to speed up math
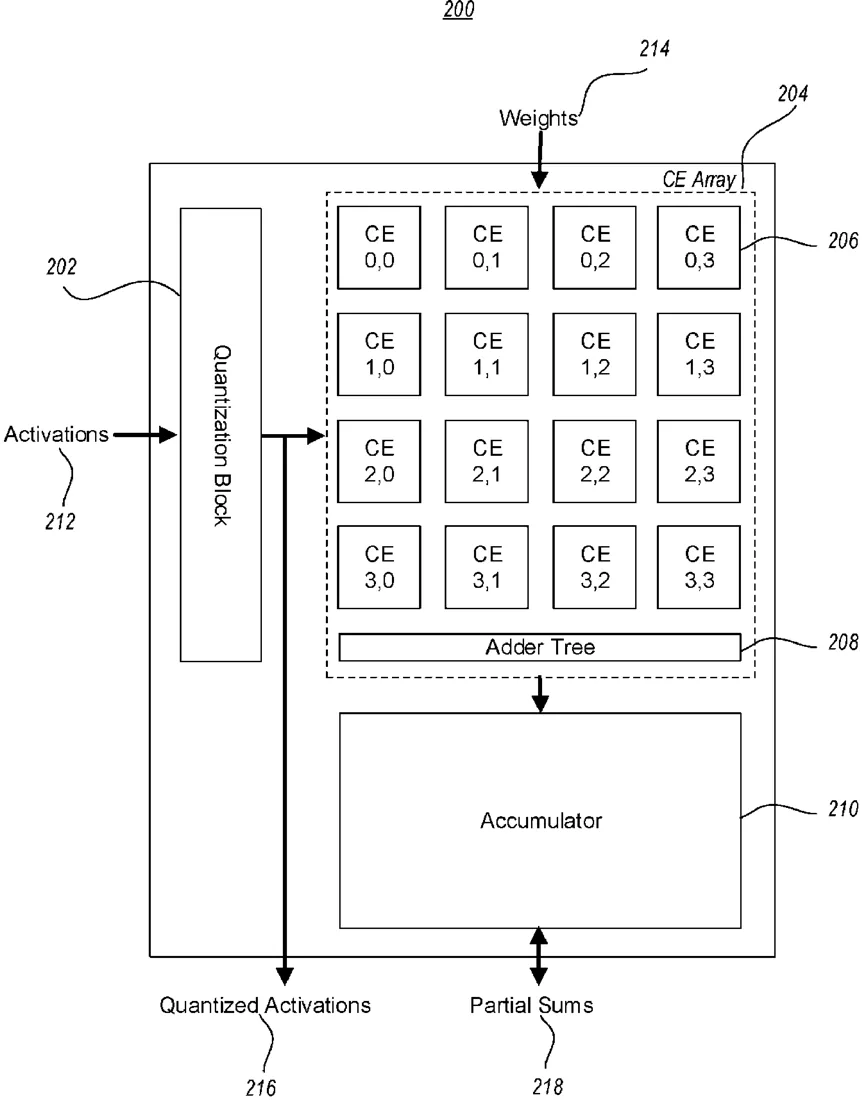
OpenAI has filed a patent for a specific computer chip layout designed to handle large math problems faster. The design keeps the fixed numbers used in AI calculations stored locally while streaming other data through the system, reducing the need to move data back and forth. It also includes a step to shrink the size of the incoming data to save power and space.
In the filing’s own words
Matrix multiplication operations in computing systems face challenges in balancing computational throughput, memory bandwidth, and power efficiency. To address these challenges, the disclosed technology provides a computing system architecture including general matrix multiply (GEMM) engines configured to accelerate matrix multiplication operations. The GEMM engines employ a weight-stationary dataflow in which weight values remain stored in compute engines while activation values are streamed through the system. A quantization block converts activation values from a first format to a second, reduced-precision format, and an accumulator stores partial sums from a compute engine array. Each compute engine includes dual weight banks enabling concurrent weight loading and computation. The compute engine array includes multiple weight interfaces coupled with different subsets of columns for parallel weight distribution. In some embodiments, the computing system includes multiple compute tiles arranged into one or more domains for scalable deployment.
What exactly they claim (claim 1)
1. A computing system, comprising: a processing system including one or more processors; a memory subsystem including at least one of a system‑level cache and high‑bandwidth memory (HBM); a plurality of compute tiles; general matrix multiply (GEMM) engines in the plurality of compute tiles and operatively coupled to the memory subsystem, the GEMM engines comprising: a compute engine array comprising a plurality of compute engines; a quantization block coupled to the compute engine array, the quantization block being configured to receive activation values and provide quantized activation values to the compute engine array; and an accumulator coupled with the compute engine array and configured to receive and store results from the compute engine array.
Facts
- Company
- OpenAI (OpenAI Opco, LLC)
- Official title
- COMPUTE ARCHITECTURE FOR WEIGHT-STATIONARY MATRIX MULTIPLY OPERATIONS
- Publication number
- US20260329966A1
- Application number
- 19529294
- Filed
- Feb 4, 2026
- Published
- Oct 22, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06F 17/16 Physics & computingMore from OpenAI in Chips & hardware
- OpenAI patents chip design that learns while processing data Sep 29, 2026
- OpenAI patents memory chip design to update AI weights while calculating Sep 17, 2026
- OpenAI patents analog circuit that learns by balancing electrical energy Sep 29, 2026
- OpenAI patents chip design that switches between math types to save power Oct 13, 2026
- OpenAI patents chip design that flips math operations without moving data Sep 17, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.