Microsoft patents memory-saving trick for AI text generation
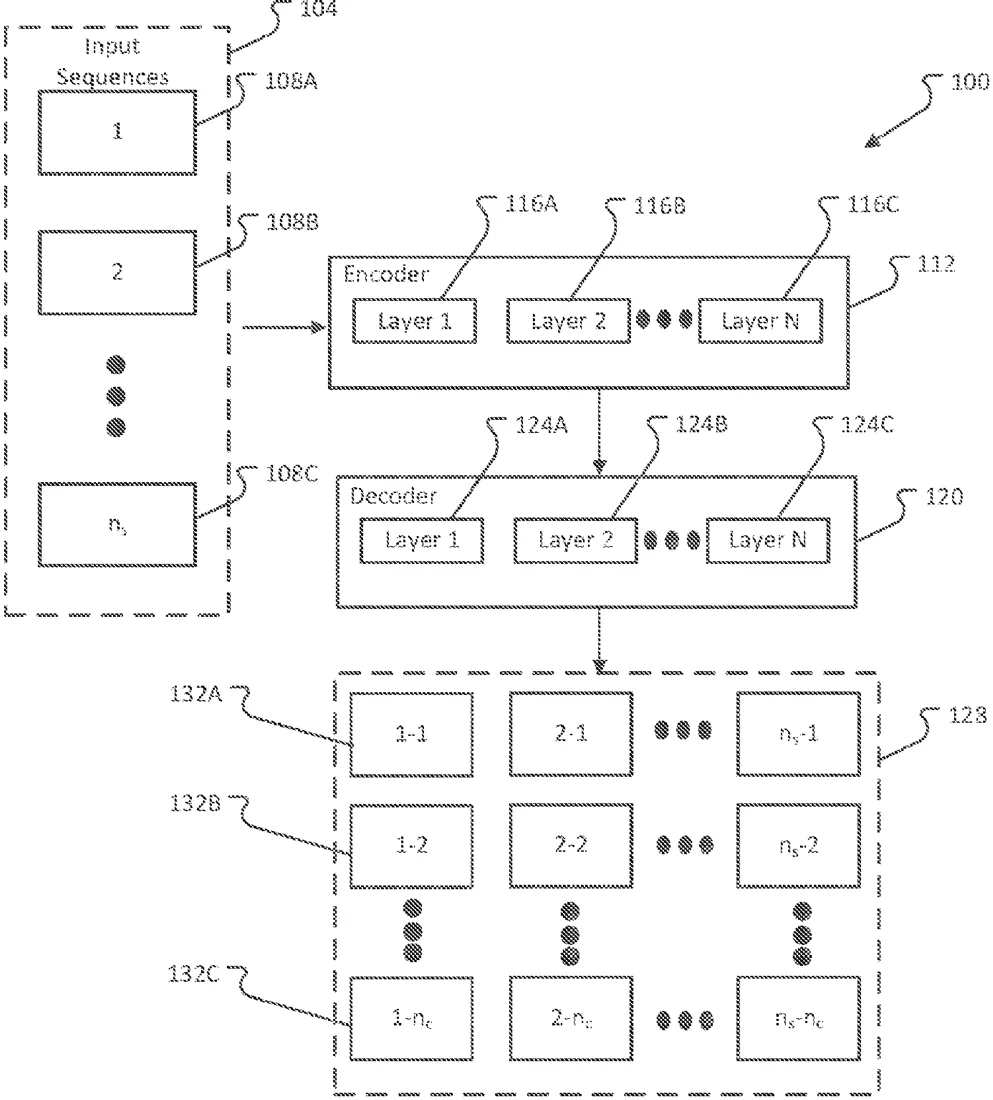
Microsoft describes a method to manage memory usage in AI models that generate text. When the system runs out of space, it deletes or shares specific parts of its temporary storage to keep running smoothly.
In the filing’s own words
Systems and methods for dynamically modifying a cache associated with a neural network model of a natural language generator are described. In examples, a neural network model employs a beam search algorithm at a decoder when decoding output and generating predicted output candidates. The decoder utilizes caching techniques to improve a speed at which the neural network operations. When an amount of memory utilized by one or more caches of the neural network model is determined to exceed a threshold memory size, a layer-specific portion of a cache associated with a layer of the neural network model is identified. The identified layer-specific portion of the cache can be deleted when the amount of memory utilized by the cache of the neural network model exceeds the threshold memory size. In examples, data in the cache is deduplicated and/or deleted.
What exactly they claim (claim 1)
1. A system comprising: a memory storing a cache including a plurality of layer-specific cache regions associated with a decoder including a plurality of layers and a cache-location table that stores a cache location identifying a first layer-specific cache region of the plurality of layer-specific cache regions that corresponds to a first layer of the plurality of layers of the decoder; one or more processors; and instructions, stored in the memory, that, as a result of being executed by the one or more processors, cause the one or more processors to: cause an encoder to generate an encoded representation of an input; for a plurality of beams of a beam search, cause the decoder to generate candidate outputs based on the encoded representation, wherein for the first layer, the plurality of beams share the first layer-specific cache region as a single layer-specific cache region identified in the cache-location table for the first layer based on an identifier; for a first beam and a second beam, access the first layer-specific cache region identified in the cache-location table to obtain cached data used by the first layer to generate a first candidate output for the first beam and a second candidate output for the second beam; and maintain, for the first layer, a number of beam-specific cache regions used during the beam search that is less than a beamwidth of the beam search based on the single layer-specific cache region that is shared.
Facts
- Company
- Microsoft (Microsoft Technology Licensing, LLC)
- Official title
- DYNAMIC CACHE MANAGEMENT IN BEAM SEARCH
- Publication number
- US20260310929A1
- Application number
- 19705439
- Filed
- Jun 11, 2026
- Published
- Oct 8, 2026
- Inventors
- 3
- Claims
- 20
Classified under
G06N 3/04 Physics & computingG06F 40/40 Physics & computingMore from Microsoft in AI & software
- Microsoft patents method to check AI answers against verified facts Oct 20, 2026
- Microsoft patents AI that presents PowerPoint slides for you Sep 3, 2026
- Microsoft patents method to check if LLM answers are based on real data Sep 10, 2026
- Microsoft patents system to blend multiple AI agents into one chat Oct 1, 2026
- Microsoft patents system that answers questions using your screen history Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.