Tesla patents method to speed up AI processing in self-driving cars
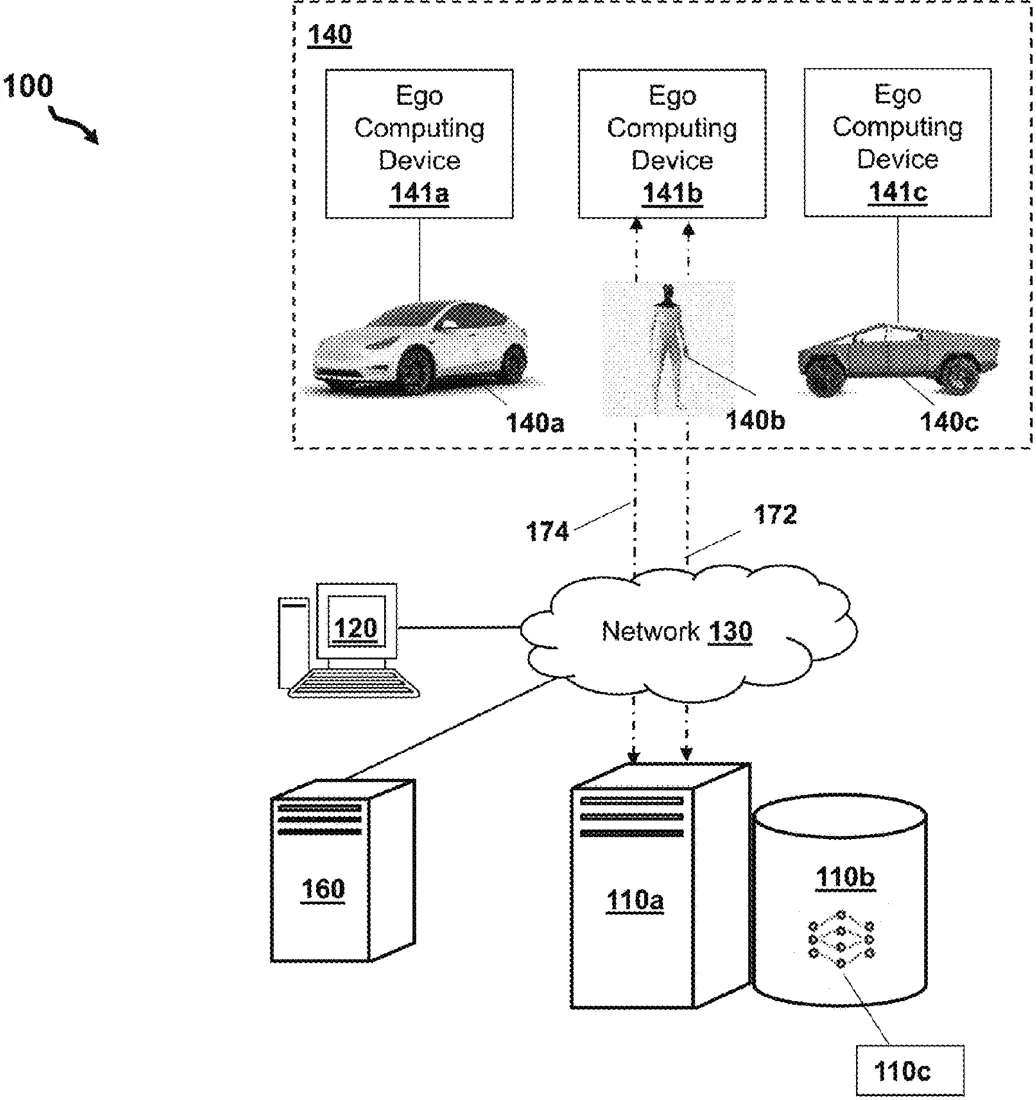
Tesla has filed a patent for a way to make its self-driving software run faster by reducing the amount of data the computer has to process. The system uses a technique called dynamic quantization, which adjusts the precision of the data in real-time to save memory and power.
In the filing’s own words
Embodiments include systems and methods for processing sensor data and generating operational instructions for automated devices. The automated device includes hardware (e.g., INT8 MAC units, FP32 SIMD processors) and software operations executing a machine-learning architecture having transformer architectures implementing mixed-precision quantization for ingesting and analyzing various types of sensor data. The machine-learning architecture implements a transformer that includes dynamic quantization layers that dynamically quantize tensors, per-token, for downstream operations of the transformer and machine-learning architecture.
What exactly they claim (claim 1)
1. A method comprising: obtaining, by a processor, a plurality of input tokens representing input data; generating, by the processor, a plurality of feature vectors based upon the plurality of input tokens, the feature vectors having a number of bits according to a first precision; executing, by the processor, a dynamic quantization to one or more of the feature vectors based upon a level of precision, to update the number of bits of the feature vectors according to a second precision corresponding to the level of precision for the input data to a subsequent computation operation; generating, by the processor, a similarity value using the feature vectors; generating, by the processor, one or more attention weights using a normalization function applied to the similarity value; generating, by the processor, a weighted sum of one or more of the feature vectors using the attention weights; and generating, by the processor, an intermediate context representation for the plurality of input tokens by aggregating the weighted sums.
Facts
- Company
- Tesla (Tesla, Inc.)
- Official title
- QUANTIZED FLASH ATTENTION
- Publication number
- US20260299946A1
- Application number
- 19321931
- Filed
- Sep 8, 2025
- Published
- Oct 1, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06F 9/30036 Physics & computingG06F 9/3001 Physics & computingMore from Tesla in AI & software
- Tesla patents method to train self-driving software using simulated driving Oct 6, 2026
- Tesla patents method to share object labels between different car sensors Sep 17, 2026
- Tesla patents faster math for car navigation AI Oct 1, 2026
- Tesla patents faster math for self-driving AI Oct 1, 2026
- Tesla patents method to speed up AI calculations in self-driving cars Oct 1, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.