Tesla patents faster math for car navigation AI
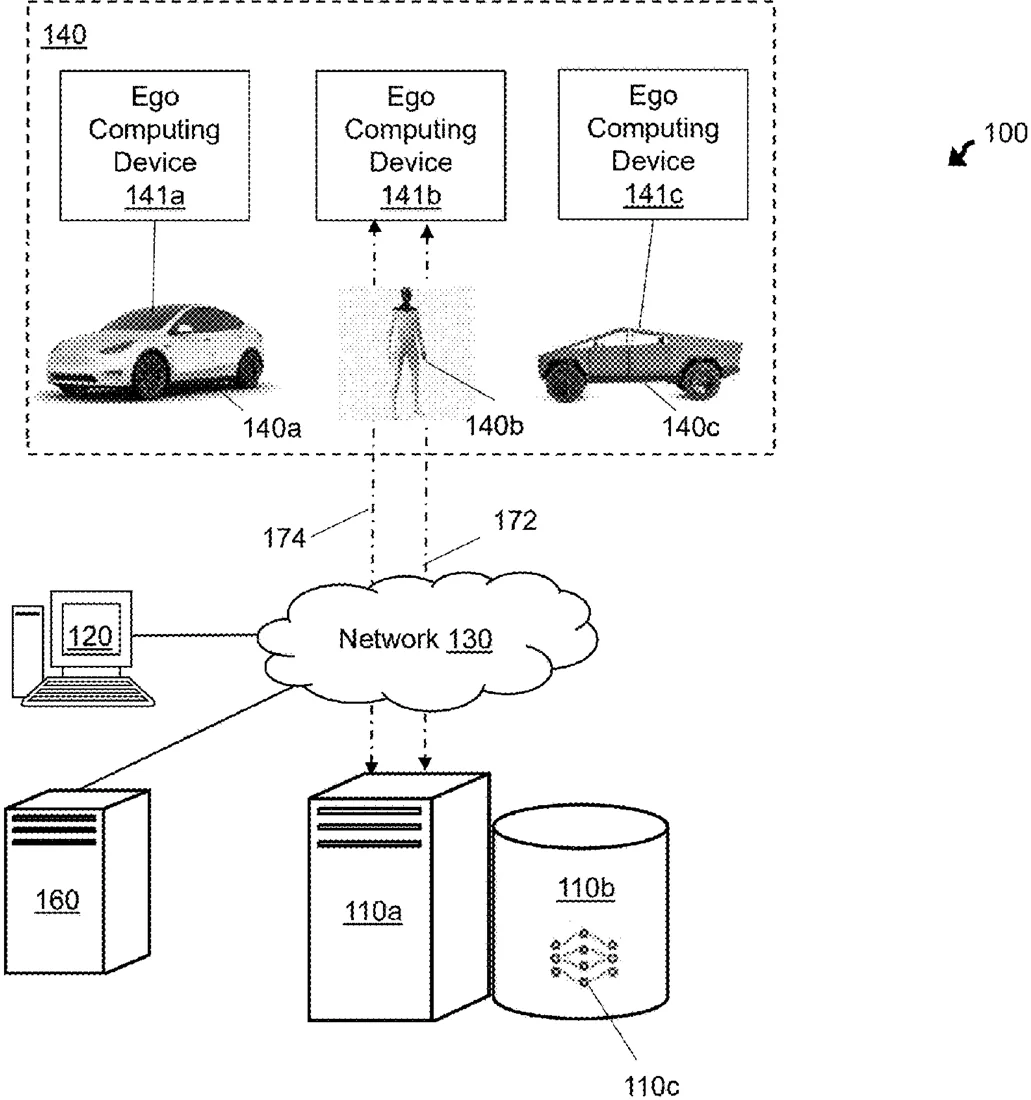
Tesla describes a method to speed up the attention mechanism in transformer models used for vehicle navigation. It replaces complex decimal calculations with simpler integer operations, such as bit shifting and base-2 exponentiation, to process sensor data more efficiently.
In the filing’s own words
Disclosed herein are methods and systems for a navigation paradigm. One method includes receiving a set of quantized values resulting from a matrix multiplication of quantized query and key vectors, the set of quantized values corresponding to sensor data associated with the ego; identifying a maximum value using an integer comparison operation; for at least one quantized value in the set of quantized values, computing a difference between the quantized value and the maximum value; executing a bit shift operation, on the difference between the quantized value and the maximum value, corresponding to a power-of-two quantization scale to generate bit-shifted values; executing a base-2 exponentiation operation to the bit shifted values to generate base-2 exponentiated values; aggregating the base-2 exponentiated values to generate an aggregated value; and executing a model using the aggregated value to output a navigational instruction to be executed by the ego.
What exactly they claim (claim 1)
1. A method of navigating an ego via ingesting sensor data, the method comprising: receiving, by one or more processors, a set of quantized values resulting from a matrix multiplication of quantized query and key vectors in an attention layer of a transformer model, the set of quantized values corresponding to sensor data associated with the ego; identifying, by the one or more processors, from the set of quantized values, a maximum value using an integer comparison operation; for at least one quantized value in the set of quantized values, computing, by the one or more processors, a difference between the quantized value and the maximum value; executing, by the one or more processors, a bit shift operation, on the difference between the quantized value and the maximum value, corresponding to a power-of-two quantization scale to generate bit-shifted values; executing, by the one or more processors, a base- 2 exponentiation operation to the bit shifted values to generate base- 2 exponentiated values; aggregating, by the one or more processors, the base- 2 exponentiated values to generate an aggregated value; and executing, by the one or more processors, a model using the aggregated value to output a navigational instruction to be executed by the ego.
Facts
- Company
- Tesla (Tesla, Inc.)
- Official title
- SYSTEMS AND METHODS FOR ATTENTION COMPUTATION IN QUANTIZED TRANSFORMER MODELS
- Publication number
- US20260296410A1
- Application number
- 19268269
- Filed
- Jul 14, 2025
- Published
- Oct 1, 2026
- Inventors
- 2
- Claims
- 20
Classified under
B60W 30/09 Operations & transportG06F 5/01 Physics & computingMore from Tesla in AI & software
- Tesla patents method to train self-driving software using simulated driving Oct 6, 2026
- Tesla patents method to share object labels between different car sensors Sep 17, 2026
- Tesla patents faster math for self-driving AI Oct 1, 2026
- Tesla patents method to speed up AI calculations in self-driving cars Oct 1, 2026
- Tesla patents method to speed up AI processing in self-driving cars Oct 1, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.