Microsoft patents method to speed up AI processing on standard chips
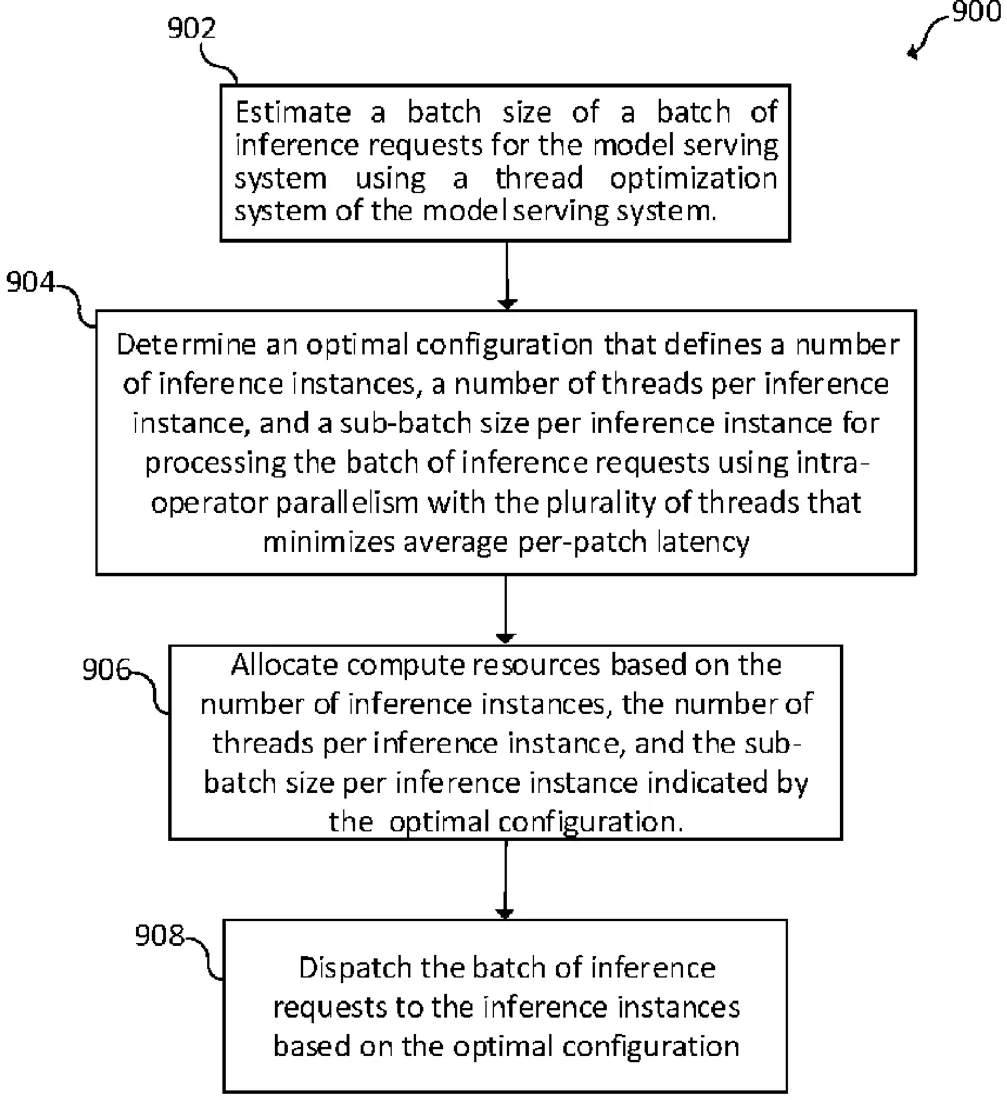
This patent describes a system that automatically decides how to split up AI calculation tasks across a computer's processor cores. It uses pre-calculated data to find the best way to group requests and assign threads, aiming to reduce the time it takes to process each batch of data.
In the filing’s own words
Systems and methods for optimizing thread allocation in a model serving system include estimating a batch size for inference requests. An optimal configuration is then determined that defines a number of inference instances, a number of threads per inference instance, and a sub-batch size per inference instance for processing a batch of inference requests of the batch size using intra-operator parallelism that minimizes average per-batch latency. The optimal configuration is determined with reference to a plurality of predetermined model profiles that define single-inference average batch latencies for different combinations of thread counts and batch sizes, the predetermined model profiles being used as input to a dynamic programming algorithm that identifies optimal configurations that minimize the average per-batch latency.
What exactly they claim (claim 1)
1. A thread optimization system for a model serving system, the thread optimization system comprising: a processor; and a memory in communication with the processor, the memory comprising executable instructions that, when executed by the processor alone or in combination with other processors, cause the thread optimization system to perform functions of: estimating a batch size for inference requests of the model serving system using a batch size estimator component of the thread optimization system, the model serving system serving a deep learning model and including a plurality of threads corresponding to a total thread count for processing inferences for the deep learning model; automatically determining, using an optimizer component of the thread optimization system, a first optimal configuration that defines a number of inference instances, a number of threads per inference instance, and a sub-batch size per inference instance for processing a batch of inference requests of the batch size using intra-operator parallelism with the plurality of threads that minimizes average per-batch latency, the first optimal configuration being determined with reference to a plurality of predetermined model profiles that define single-inference average batch latencies for different combinations of thread counts and batch sizes, the plurality of predetermined model profiles being used as input to a dynamic programming algorithm that identifies optimal configurations that minimize the average per-batch latency; and allocating compute resources based on the number of inference instances, the number of threads per inference instance, and the sub-batch size per inference instance indicated by the first optimal configuration.
Facts
- Company
- Microsoft (Microsoft Technology Licensing, LLC)
- Official title
- Automatic latency optimization for CPU-based DNN serving
- Patent number
- US12769589B2
- Application number
- 18452326
- Filed
- Aug 18, 2023
- Granted
- Oct 20, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06F 9/5061 Physics & computingG06F 9/5011 Physics & computingG06N 3/04 Physics & computingMore from Microsoft in AI & software
- Microsoft patents method to check AI answers against verified facts Oct 20, 2026
- Microsoft patents AI that presents PowerPoint slides for you Sep 3, 2026
- Microsoft patents method to check if LLM answers are based on real data Sep 10, 2026
- Microsoft patents system to blend multiple AI agents into one chat Oct 1, 2026
- Microsoft patents system that answers questions using your screen history Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.