Microsoft patents method to improve speech recognition for rare languages
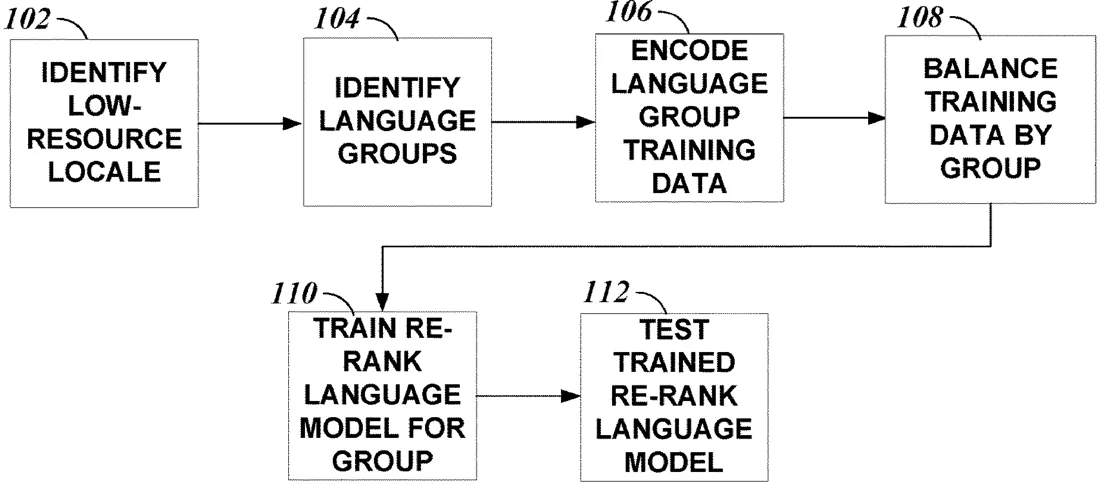
Microsoft describes a system that groups languages with limited digital data based on how similar they are to one another. It combines the available training data from these similar languages to teach a model that improves the accuracy of speech recognition systems.
In the filing’s own words
Generally discussed herein are devices, systems, and methods for multi-lingual model generation. A method can include determining, for low-resource languages, respective a language similarity value indicating language similarity between each of the low-resource languages, clustering the low-resource languages into groups based on the respective language similarity value, aggregating training data of languages corresponding to a given group resulting in aggregated training data, and training a re-ranking language model based on the aggregated training data resulting in a trained re-ranking language model.
What exactly they claim (claim 1)
1. A computer implemented method for multi-lingual language model generation, the method comprising: identifying an available amount of language model training data for each language of a corpus of languages; and identifying, based on the available amount of language model training data, which languages of the corpus of languages are low-resource languages; determining, for the low-resource languages, respective language similarity values, the respective language similarity values indicating language similarity between pairs of different low-resource languages of the low-resource languages; clustering, using the respective language similarity values as input, the low-resource languages into groups; aggregating training data of languages corresponding to a given group of the groups resulting in aggregated training data; and training a re-ranking language model based on the aggregated training data resulting in a trained re-ranking language model that operates to re-rank outputs from a separate speech recognition model.
Facts
- Company
- Microsoft (Microsoft Technology Licensing, LLC)
- Official title
- Low-resource, multi-lingual transformer models
- Patent number
- US12748800B2
- Application number
- 17840166
- Filed
- Jun 14, 2022
- Granted
- Sep 29, 2026
- Inventors
- 5
- Claims
- 17
Classified under
G06F 16/35 Physics & computingG06F 16/335 Physics & computingG06F 18/214 Physics & computingG06F 18/23213 Physics & computingG06F 40/284 Physics & computingG06F 40/289 Physics & computingMore from Microsoft in AI & software
- Microsoft patents method to check AI answers against verified facts Oct 20, 2026
- Microsoft patents AI that presents PowerPoint slides for you Sep 3, 2026
- Microsoft patents method to check if LLM answers are based on real data Sep 10, 2026
- Microsoft patents system to blend multiple AI agents into one chat Oct 1, 2026
- Microsoft patents system that answers questions using your screen history Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.