Google patents method to align words with image regions in AI art
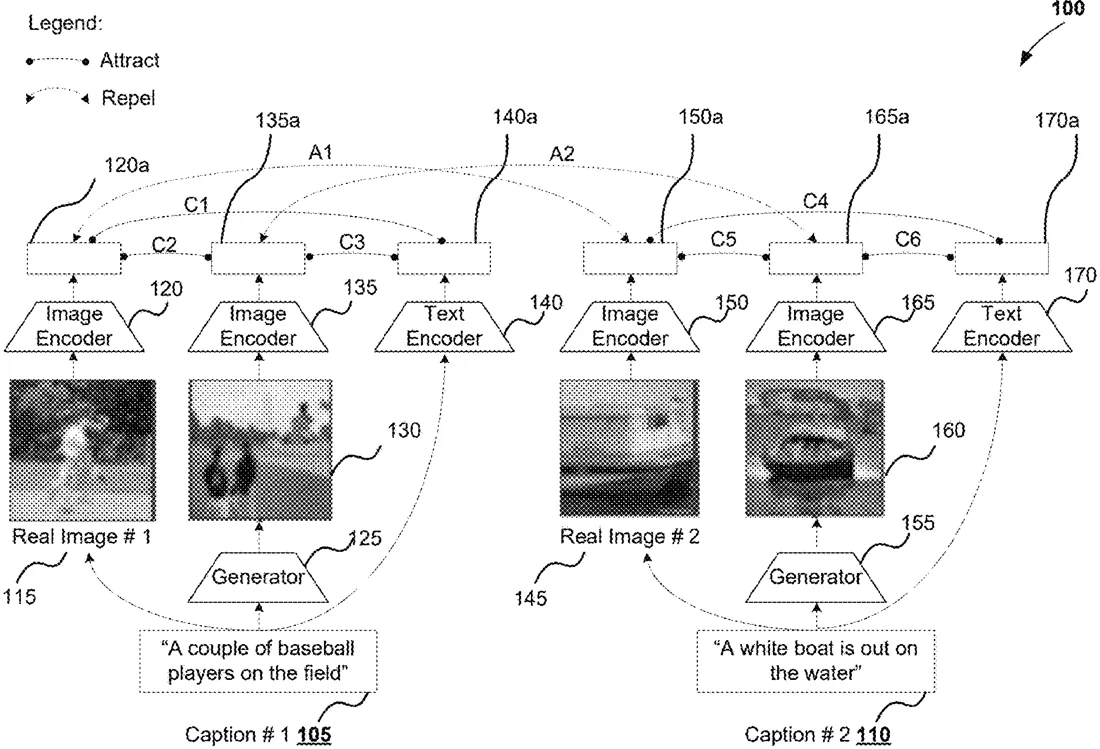
Google describes a method for generating images from text by using a neural network that links specific words to specific parts of the picture. The system is trained to ensure that images matching the same description look similar, while images from different descriptions remain distinct.
In the filing’s own words
A computer-implemented method includes receiving, by a computing device, a particular textual description of a scene. The method also includes applying a neural network for text-to-image generation to generate an output image rendition of the scene, the neural network having been trained to cause two image renditions associated with a same textual description to attract each other and two image renditions associated with different textual descriptions to repel each other based on mutual information between a plurality of corresponding pairs, wherein the plurality of corresponding pairs comprise an image-to-image pair and a text-to-image pair. The method further includes predicting the output image rendition of the scene.
What exactly they claim (claim 1)
1. A computer-implemented method, comprising: receiving, by a computing device, a textual description of a scene comprising a sequence of words; generating a random noise input; and processing the random noise input and the textual description using a generative neural network to generate an output image rendition of the scene, wherein the generative neural network comprises a word-region attention mechanism configured to determine an alignment between specific words in the sequence of words and specific regions of the output image rendition, and wherein the generative neural network has been trained using a contrastive loss objective that maximizes mutual information between the output image rendition and the textual description by optimizing a correspondence between features of the output image rendition and features of the textual description.
Facts
- Company
- Google (Google LLC)
- Official title
- Cross-Modal Contrastive Learning for Text-to-Image Generation based on Machine Learning Models
- Publication number
- US20260330706A1
- Application number
- 19461297
- Filed
- Jan 27, 2026
- Published
- Oct 22, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06T 11/00 Physics & computingG06F 18/2148 Physics & computingG06F 18/22 Physics & computingG06N 3/08 Physics & computingG10L 15/26 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.