Nvidia patents chip design to speed up AI calculations
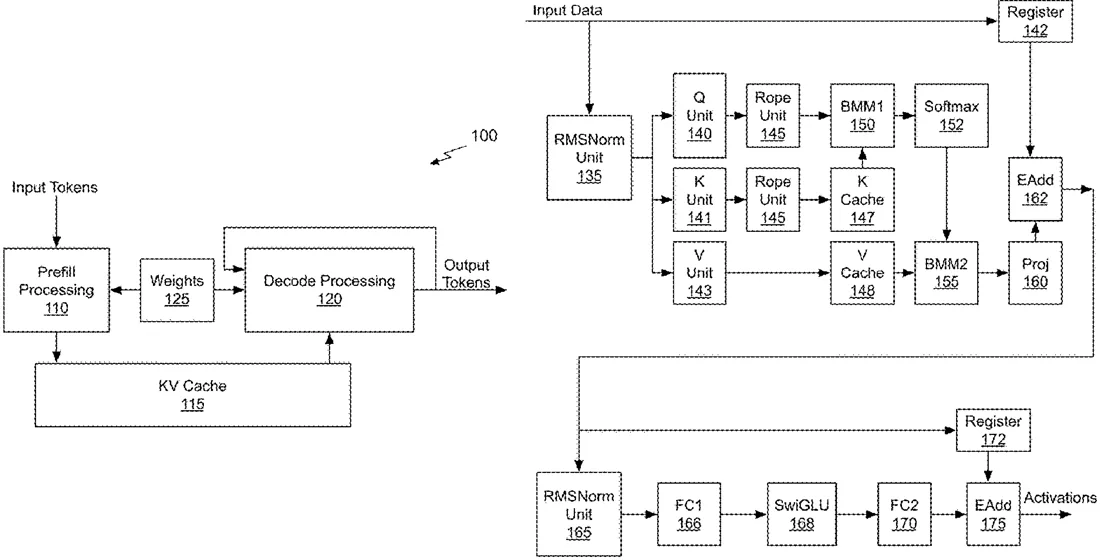
Nvidia describes a computer chip layout designed to run AI models faster by keeping data close to the processing units. The system uses specific blocks called compute tiles that handle math operations locally to avoid moving data around the chip. It also includes a flexible network that sends results directly to the next step in the calculation.
In the filing’s own words
A low-latency processing system reduces data movement, improves memory bandwidth utilization, and enables, e.g., scalable, low-latency neural network inference. Compute tiles are configured to efficiently execute activation functions in parallel. Each compute tile includes an array of basic units equipped with local SRAM, vector registers, and multiply-accumulate (MAC) units, enabling localized computation to minimize data movement and reduce latency. IMLP tiles efficiently perform data format conversions and reduction operations as part of intermediate layer processing. A configurable network transmits data directly from source to destination register(s) within compute and IMLP tiles. Connections are, e.g., pre-configured for one or more cycles of neural network inference.
What exactly they claim (claim 1)
1. A computer-implemented method for performing low latency inference (LLI) operations, comprising: distributing input data across a number of compute tiles organized into groups of compute tiles to compute tensor operations for at least a processing operation of a neural network model using the input data, wherein the number is based on a tensor shape of at least one tensor operation; combining partial results computed by at least one group of compute tiles to produce one or more per-group results, wherein at least one group of compute tiles is associated with an inter-matrix layer processing (IMLP) tile; and distributing the per-group results through a configurable network directly to registers in one or more IMLP tiles or to additional compute tiles to perform additional calculations for a next processing operation of the neural network model.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- LOW-LATENCY COMPUTE ARCHITECTURES AND USE FOR NEURAL NETWORK INFERENCE
- Publication number
- US20260330205A1
- Application number
- 19371545
- Filed
- Oct 28, 2025
- Published
- Oct 22, 2026
- Inventors
- 4
- Claims
- 22
Classified under
G06N 3/063 Physics & computingG06F 15/161 Physics & computingG06F 15/17337 Physics & computingMore from Nvidia in Chips & hardware
- Nvidia patents method to skip zero data in neural network math Oct 13, 2026
- Nvidia patents hardware to speed up motion blur in ray tracing Oct 13, 2026
- Nvidia patents method to sync data across split processor chips Sep 17, 2026
- Nvidia patents chip math trick to speed up AI calculations Oct 8, 2026
- Nvidia patents data center cooling that uses cryogenic fluids Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.