Google patents transformer model that reuses calculations to save power
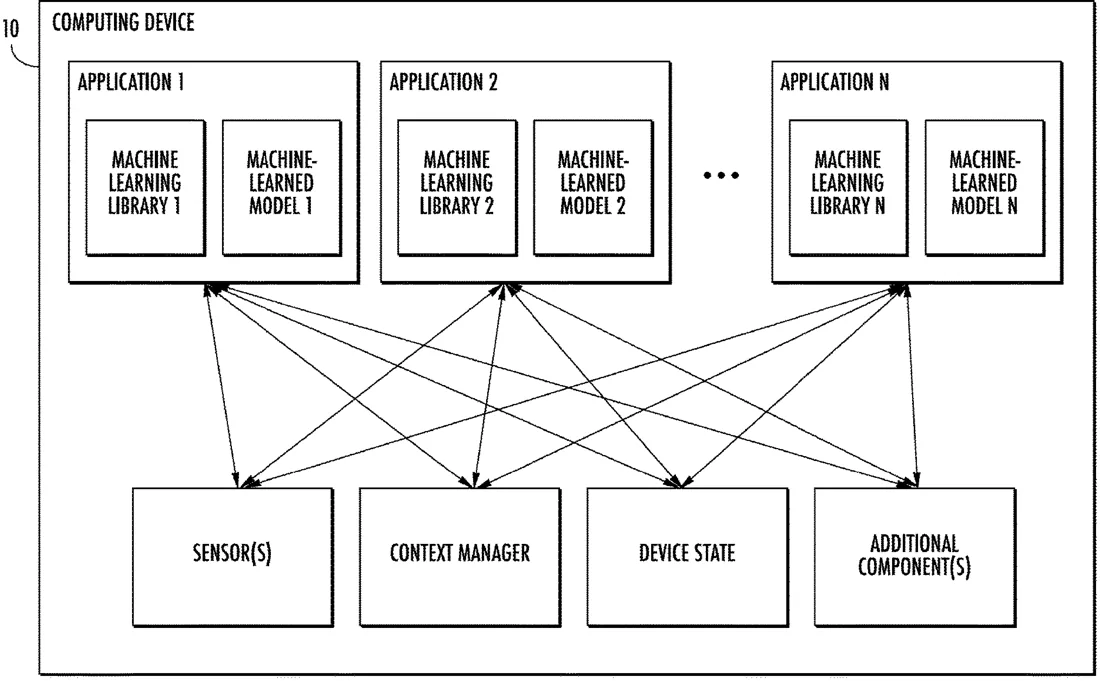
This filing describes a method for making AI models run faster by reusing specific calculations from one layer of the network in later layers. Instead of recalculating the same data points, the system transforms and reuses these existing values to reduce the total amount of work the computer has to do.
In the filing’s own words
Provided are systems and methods that improve the computational efficiency of Transformers or other attention-based neural networks or machine learning models by re-using a number of attention scores between layers and/or heads of the model. To reduce the computational cost of self-attention-based models while achieving comparable or even superior results, example aspects of the present disclosure propose a novel architecture that reuses attention scores computed in one layer in one or multiple subsequent layers.
What exactly they claim (claim 1)
1. A computing system for performing attention with improved computational efficiency, the computing system comprising: one or more processors; and one or more non-transitory computer-readable media that collectively store: a machine-learned model comprising a first attention layer and a second attention layer; and instructions that, when executed by the one or more processors, cause the computing system to perform operations, the operations comprising: processing, by the machine-learned model, a model input to generate a first layer input to the first attention layer; generating, by the first attention layer, a first layer output based on first computations of the first attention layer; generating, by the second attention layer, a second layer output based on transforming, reusing the first computations of the first attention layer, an input to the second attention layer; generating a model output based on the second layer output.
Facts
- Company
- Google (Google LLC)
- Official title
- Leveraging Redundancy in Attention with Reuse Transformers
- Publication number
- US20260330180A1
- Application number
- 19730248
- Filed
- Jul 2, 2026
- Published
- Oct 22, 2026
- Inventors
- 8
- Claims
- 20
Classified under
G06N 3/04 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.