Google patents faster way to find similar data points in large datasets
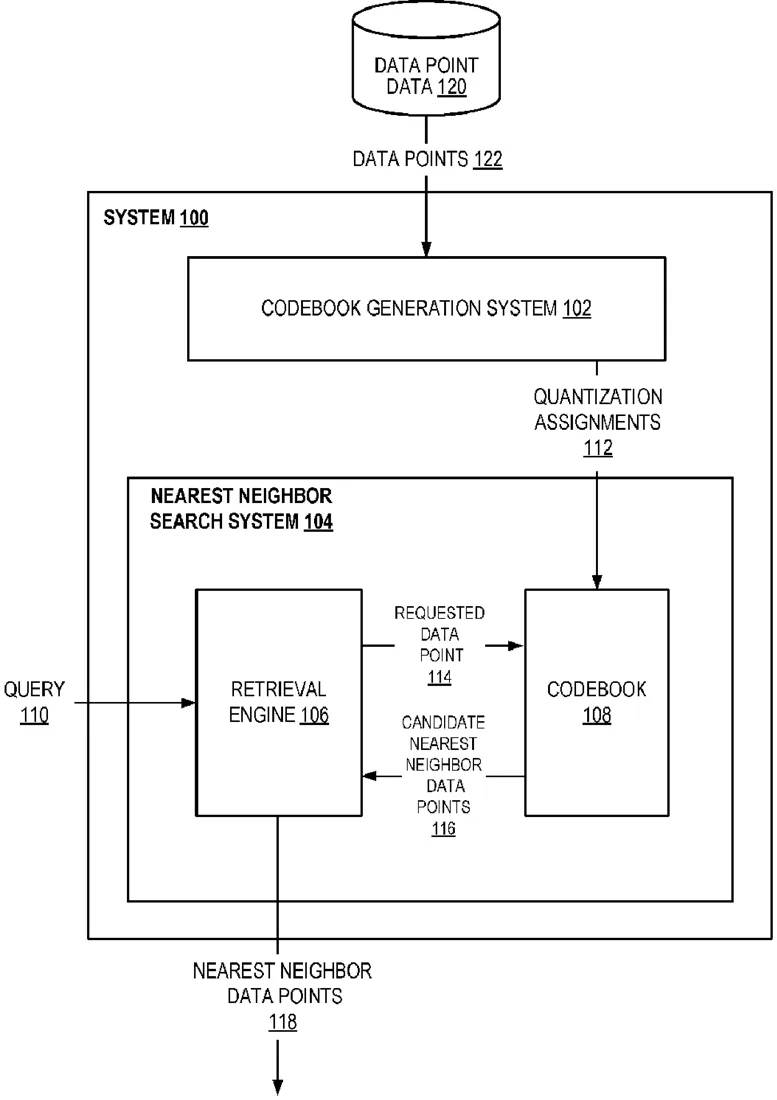
Google has filed a patent for a method to speed up searching for similar items in huge datasets. The system uses a technique called vector quantization to group data points into sections, allowing computers to quickly identify the closest matches to a query without checking every single item. This approach helps manage large amounts of data more efficiently by organizing it into manageable chunks.
In the filing’s own words
Methods, systems, and apparatus, including computer programs encoded on a computer storage medium, for performing a nearest neighbor search procedure. In one aspect, a method includes receiving a query for one or more nearest neighbor data points to a requested data point from a dataset of multiple data points, maintaining data representing a codebook, where the codebook is associated with a first set and a second set of vector quantization assignments, where the codebook includes multiple centers and each center represents a different partition of the dataset, where the first set of vector quantization assignments assigns each data point to an index of a closest center of the multiple centers and the second set of vector quantization assignments assigns each data point to an index of another center of the plurality of centers, and determining one or more nearest neighbor data points for the query using the data.
What exactly they claim (claim 1)
1. A computer-implemented method for performing a nearest neighbor search procedure, the method comprising: receiving a query for one or more nearest neighbor data points to a requested data point from a dataset of a plurality of data points; maintaining data representing a codebook, wherein the codebook is associated with a first set of vector quantization assignments and a second set of vector quantization assignments, wherein the codebook comprises a plurality of centers and each center represents a different partition of the dataset of a plurality of data points, wherein the first set of vector quantization assignments assigns each data point to an index of a closest center of the plurality of centers and the second set of vector quantization assignments assigns each data point to an index of another center of the plurality of centers; and determining one or more nearest neighbor data points for the query using the data.
Facts
- Company
- Google (Google LLC)
- Official title
- APPROXIMATE NEAREST NEIGHBOR SEARCH USING SPILLED ASSIGNMENTS
- Publication number
- US20260329875A1
- Application number
- 19484747
- Filed
- May 17, 2024
- Published
- Oct 22, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06F 16/2462 Physics & computingG06F 16/2237 Physics & computingG06F 16/24556 Physics & computingG06F 18/24147 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.