Samsung patents method to train AI models to distinguish images from text
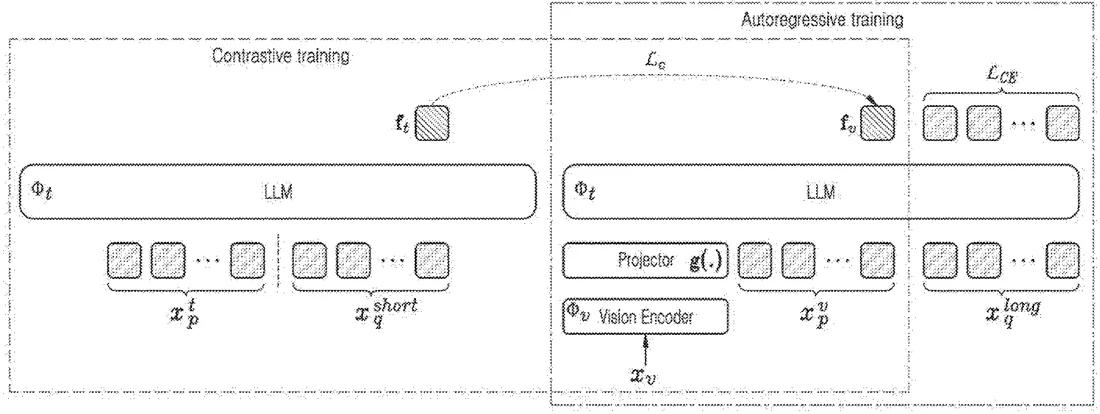
Samsung describes a way to improve large vision-language models by training them on both short and long text descriptions of images. The process uses two different types of mathematical checks, or losses, to help the model better understand how images match their written descriptions.
In the filing’s own words
A method for generating LVLM is provided. The method may comprise obtaining a pre-trained LVLM for generating at least one of images or text. The method may comprise obtaining a training dataset comprising input images. For each input image of the training dataset having the short caption, the method may comprise training the pre-trained LVLM to perform discriminative image-based tasks, by: generating, using the pre-trained LVLM, an image embedding for the input image and a text embedding for the short caption and minimising a contrastive training loss using the image embedding and the text embedding. For each input image of the training dataset having the long caption, the method may comprise training the pre-trained LVLM to perform discriminative image-based tasks, by: generating, using the LLM, a predicted long caption for the input image and minimising an autoregressive training loss between the long caption and the predicted long caption.
What exactly they claim (claim 1)
1. A method for generating a large vision language model, LVLM, the method comprising: obtaining a pre-trained LVLM for generating at least one of images or text, wherein the pre-trained LVLM comprises a large language model, LLM, and a vision encoder; obtaining a training dataset comprising input images, wherein each input image has at least one text caption and wherein each text caption is either a short caption or a long caption; and training the pre-trained LVLM to perform discriminative image-based tasks, by: for each input image of the training dataset having the short caption: generating, using the pre-trained LVLM, an image embedding for the input image and a text embedding for the short caption; and minimising a contrastive training loss using the image embedding and the text embedding; and for each input image of the training dataset having the long caption: generating, using the LLM, a predicted long caption for the input image; and minimising an autoregressive training loss between the long caption and the predicted long caption; wherein the contrastive training loss and the autoregressive training loss are minimised jointly.
Facts
- Company
- Samsung (SAMSUNG ELECTRONICS CO., LTD.)
- Official title
- METHOD FOR GENERATING A DISCRIMINATIVE LARGE VISION-LANGUAGE MODEL
- Publication number
- US20260320989A1
- Application number
- 19633164
- Filed
- Mar 30, 2026
- Published
- Oct 15, 2026
- Inventors
- 7
- Claims
- 20
Classified under
G06V 10/778 Physics & computingG06V 20/41 Physics & computingMore from Samsung in AI & software
- Samsung patents tool to erase objects from photos using AI Sep 24, 2026
- Samsung patents drawing objects into photos with AI Oct 15, 2026
- Samsung patents AI that creates personalized exercise videos Sep 10, 2026
- Samsung patents AI summaries for paused TV shows based on your viewing habits Sep 24, 2026
- Samsung patents turning chat conversations into image prompts Oct 1, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.