Google patents method to make AI agents learn from less data
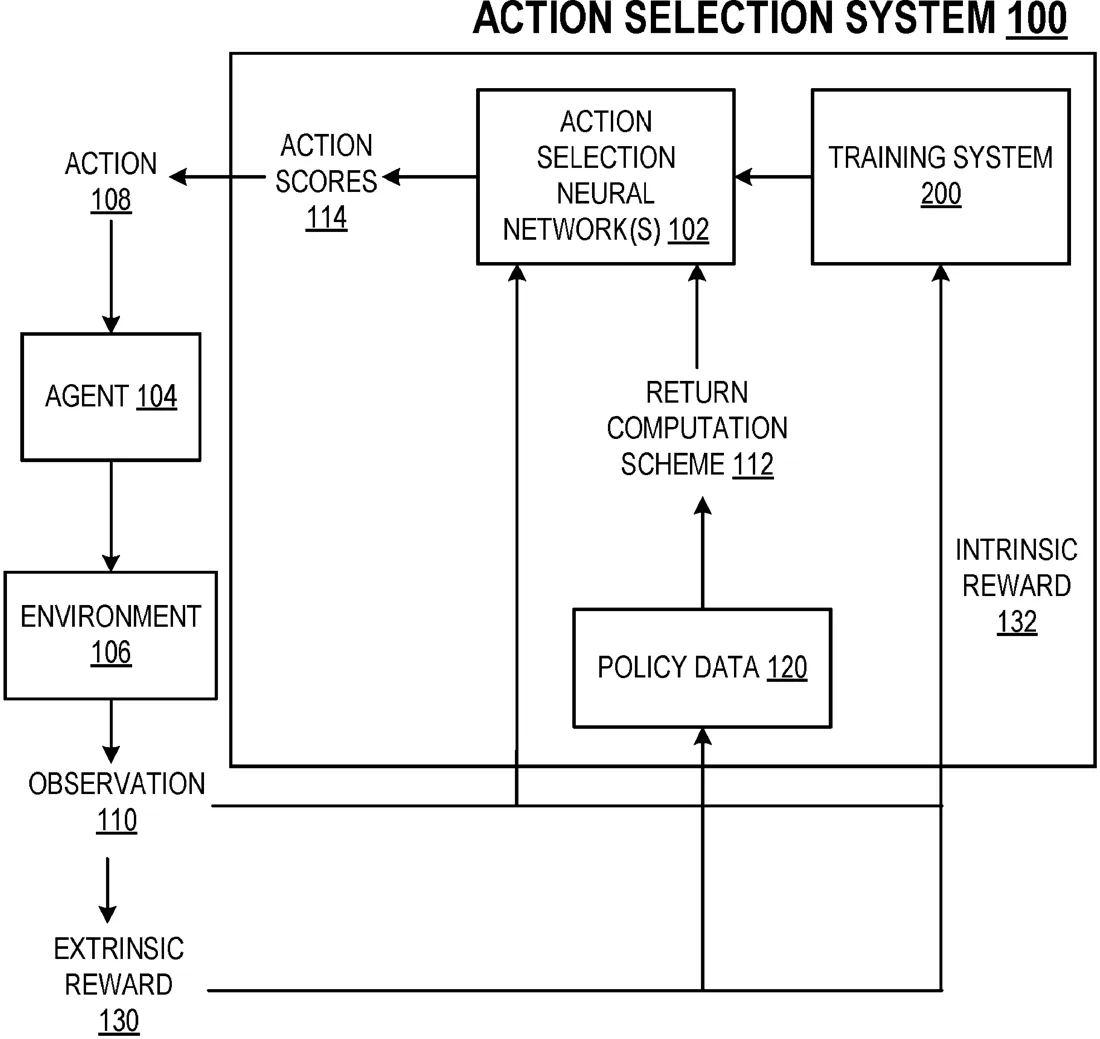
This filing describes a technique for training AI agents that choose actions based on their environment. It uses a system that compares different ways of calculating rewards to decide which data points are most useful for learning, aiming to reduce the amount of experience needed to train the model.
In the filing’s own words
Methods, systems, and apparatus, including computer programs encoded on a computer storage medium, for data-efficient reinforcement learning with adaptive return computation schemes.
What exactly they claim (claim 1)
1. A method for training an action selection neural network system having a plurality of network parameters and for controlling an agent interacting with an environment, the method comprising: obtaining a set of one or more transition sequences, each transition sequence comprising a respective transition at each of a plurality of time steps, wherein each transition includes: (i) an observation received at the time step, (ii) an action performed in response to the observation, and (iii) one or more rewards received as a result of performing the action; computing a reinforcement learning loss for the set of transition sequences, comprising, for each transition in each transition sequence and for each of one or more return computation schemes in a set of one or more return computation schemes: processing an action selection input comprising the observation at the time step using an action selection neural network of the action selection neural network system that corresponds to the return computation scheme and in accordance with current values of the network parameters to generate an action score for the action performed in response to the observation; processing the action selection input using a target action selection neural network that corresponds to the return computation scheme to generate a target action score for the action performed in response to the observation, wherein the target action selection neural network has target values of the network parameters that are constrained to change more slowly than the current values of the network parameters during the training; and determining whether to include a loss for the transition and for the return computation scheme in the reinforcement learning loss based on the action score for the action performed in response to the observation and the target action score for the action performed in response to the observation; and training the action selection neural network system using the computed reinforcement loss.
Facts
- Company
- Google (DeepMind Technologies Limited)
- Official title
- DATA-EFFICIENT REINFORCEMENT LEARNING WITH ADAPTIVE RETURN COMPUTATION SCHEMES
- Publication number
- US20260320402A1
- Application number
- 19112006
- Filed
- Sep 15, 2023
- Published
- Oct 15, 2026
- Inventors
- 5
- Claims
- 26
Classified under
G06N 3/092 Physics & computingG06N 3/045 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.