Google patents system that controls devices using images and implied commands
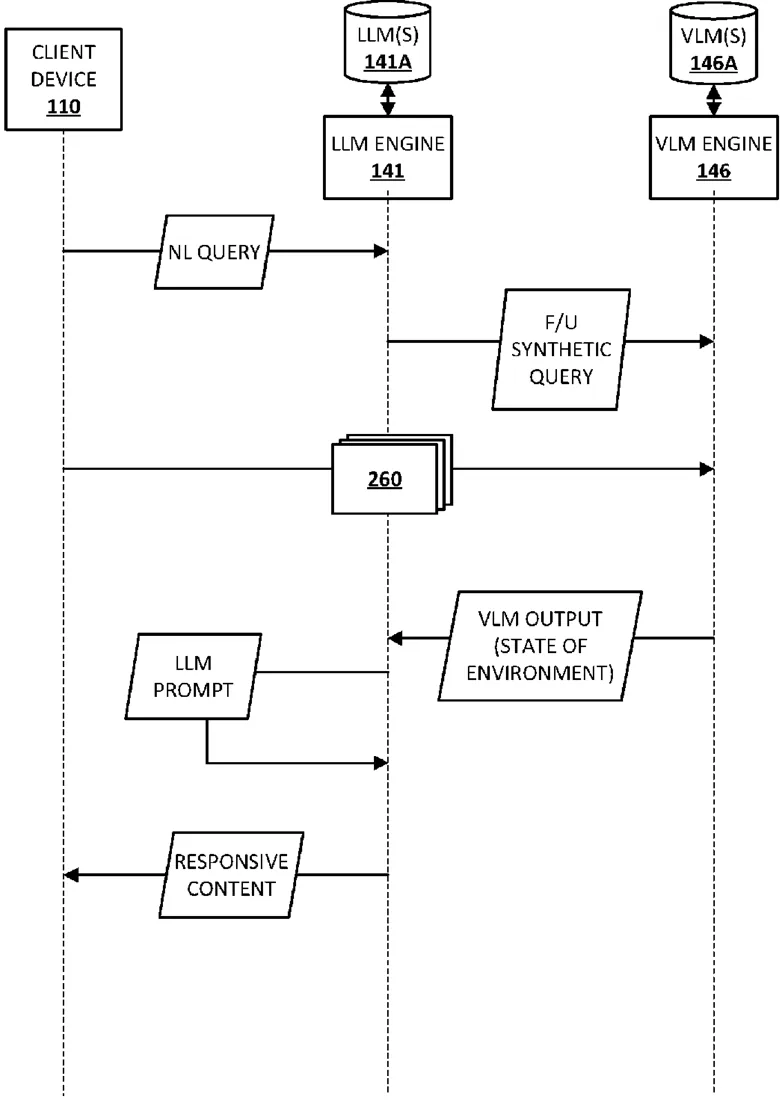
This filing describes a method where a computer looks at images to understand your surroundings and guesses what you might want to do next. It combines this visual understanding with text models to automatically send commands to other devices without you having to type or speak.
In the filing’s own words
Implementations relate to leveraging large language model(s) (LLMs) and vision language model(s) (VLMs) to facilitate human-to-computer dialogs. In various implementations, one or more digital images may be processed using one or more VLMs to generate VLM output indicative of a state of an environment. An LLM prompt may be assembled based on the VLM output and a natural language input. The LLM prompt may be processed using one or more LLMs to generate content that is responsive to the natural language input. The content that is responsive to the natural language input may subsequently be rendered at one or more output devices.
What exactly they claim (claim 1)
1. A method implemented using one or more processors and comprising: receiving one or more digital images; determining a current context of a user in an environment; generating an implied natural language input automatically based on the current context; processing the implied natural language input using one or more large language models (LLMs) to generate a natural language output indicative of the current context; assembling a vision language model (VLM) prompt to include the one or more digital images and the natural language output indicative of the current context; processing the VLM prompt using one or more VLMs to generate VLM output indicative of a state of the environment; assembling an LLM prompt based on the VLM output, wherein the assembling includes assembling one or more terms from the VLM output into the LLM prompt; processing the LLM prompt using one or more of the LLMs to generate output that is responsive to the implied natural language input and operable to control one or more operations of one or more devices; and causing the output that is responsive to the implied natural language input to control the one or more operations of the one or more devices.
Facts
- Company
- Google (GOOGLE LLC)
- Official title
- MULTIMODAL DIALOGS USING LARGE LANGUAGE MODEL(S) AND VISUAL LANGUAGE MODEL(S)
- Publication number
- US20260320311A1
- Application number
- 19718868
- Filed
- Jun 24, 2026
- Published
- Oct 15, 2026
- Inventors
- 12
- Claims
- 21
Classified under
G06F 40/40 Physics & computingG06F 40/30 Physics & computingG06F 40/35 Physics & computingG06V 10/82 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.