Samsung patents method for managing multiple AI chat requests
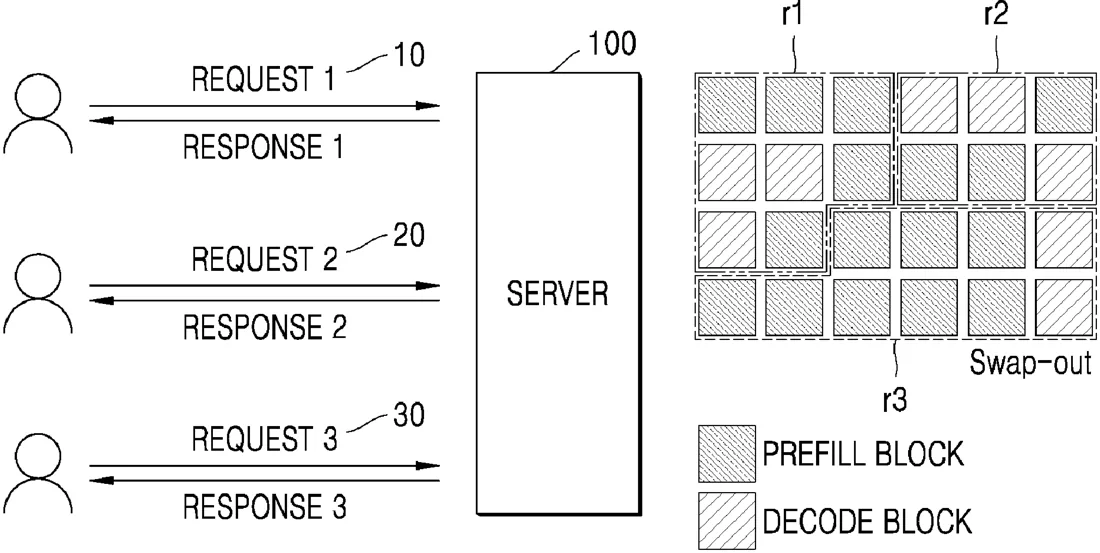
Samsung has filed a patent for a scheduling algorithm that manages how a server processes multiple requests for large language models. The system calculates the cost of swapping active tasks in and out of memory to ensure efficient processing of user queries.
In the filing’s own words
Provided is a scheduling algorithm for handling multiple user requests for a large language model (LLM). The swap cost-aware scheduling algorithm performs operations at each scheduling time stage, the operations including: based on a swap-in cost of each of swapped requests, determining a request to be swapped in, determining a number of first blocks corresponding to requests being executed and the request to be swapped in, determining a swap-out cost of each of the requests being executed when a number of second blocks is less than the number of the first blocks, wherein the second blocks are available blocks, determining a request to be swapped out from among the requests being executed, based on the swap-out cost, switching contexts by performing swap-in and swap-out, and generating the tokens that constitute the response to each request through the decoding operation.
What exactly they claim (claim 1)
1. A method by which a server handles multiple user requests for a large language model (LLM), the method comprising: receiving a plurality of requests; and generating a response to each of the plurality of requests by handling the plurality of requests by performing swap cost-aware scheduling, wherein the generating of the response to each of the plurality of requests comprises generating tokens that constitute the response to each of the plurality of requests through a decoding operation managed by a scheduler, and wherein the performing of the swap cost-aware scheduling comprises performing operations at each scheduling time stage, the operations comprising: based on a swap-in cost of each of swapped requests, determining a request to be swapped in; determining a number of first blocks corresponding to requests being executed and the request to be swapped in; determining a swap-out cost of each of the requests being executed when a number of second blocks is less than the number of the first blocks, wherein the second blocks are available blocks; determining a request to be swapped out from among the requests being executed, based on the swap-out cost; switching contexts by performing swap-in and swap-out; and generating the tokens that constitute the response to each request through the decoding operation.
Facts
- Company
- Samsung (SAMSUNG ELECTRONICS CO., LTD.)
- Official title
- METHOD AND SERVER FOR HANDLING MULTIPLE USER REQUESTS FOR LLM
- Publication number
- US20260319838A1
- Application number
- 19662474
- Filed
- Apr 29, 2026
- Published
- Oct 15, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06F 9/4881 Physics & computingMore from Samsung in AI & software
- Samsung patents tool to erase objects from photos using AI Sep 24, 2026
- Samsung patents drawing objects into photos with AI Oct 15, 2026
- Samsung patents AI that creates personalized exercise videos Sep 10, 2026
- Samsung patents AI summaries for paused TV shows based on your viewing habits Sep 24, 2026
- Samsung patents turning chat conversations into image prompts Oct 1, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.