Google patents method to combine vision and language AI models
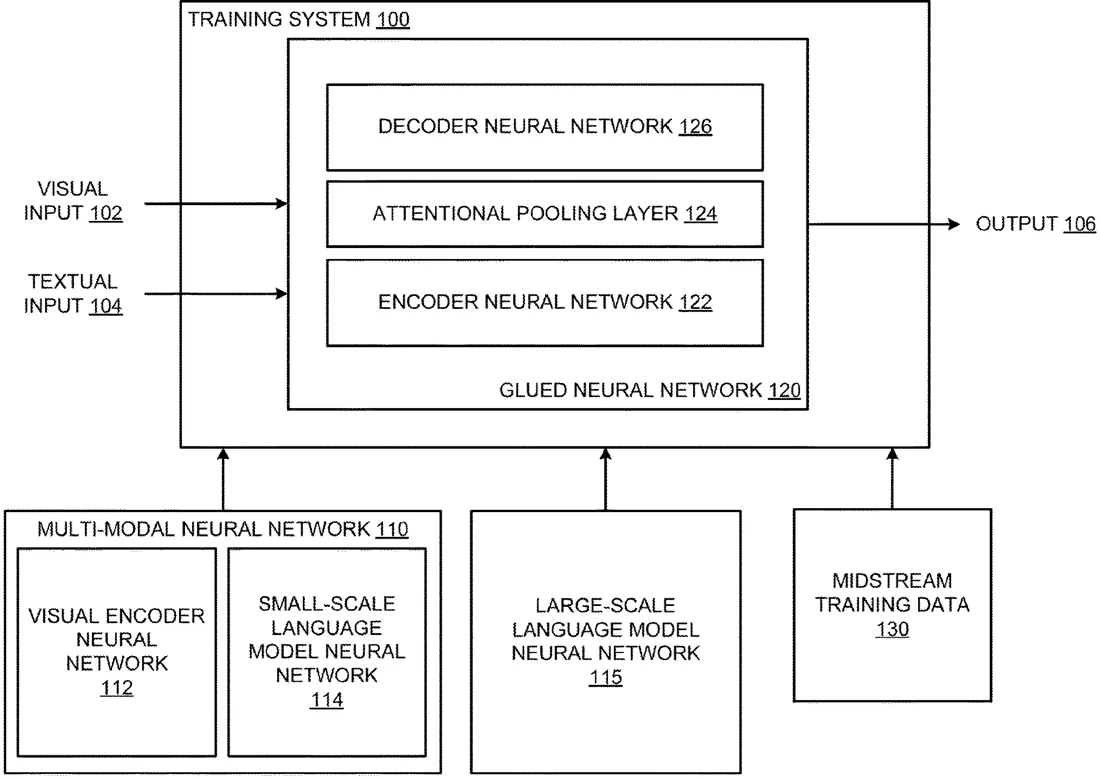
Google describes a way to build a new AI system by taking parts from two existing models: one that understands images and basic text, and another that handles complex language. The company explains how to link these parts together and train them as a single unit to handle tasks involving both pictures and words.
In the filing’s own words
Methods, systems, and apparatus, including computer programs encoded on computer storage media, for generating and training a glued neural network that reuses components taken from a first pre-trained neural network and a second pre-trained neural network. For example, the first pre-trained neural network can be a multi-modal neural network that includes a visual encoder neural network and a small-scale language model neural network. The second pre-trained neural network can be a large-scale language model neural network.
What exactly they claim (claim 1)
1. A computer-implemented method comprising: obtaining data specifying a visual encoder neural network that has been trained jointly with a small-scale language model neural network as part of a multi-modal neural network that has been trained to perform one or more upstream multi-modal tasks; obtaining data specifying a large-scale language model neural network that has been trained to perform one or more upstream language modeling tasks; generating a glued neural network that includes parameters taken from both the visual encoder neural network and the large-scale language model neural network; training the glued neural network to perform a midstream multi-modal task, including adjusting learned values of only a proper subset of the parameters of the glued neural network by using a set of midstream training pairs that each include a respective visual input and a respective text sequence, while holding learned values of the parameters that are not in the proper subset fixed; and after training the glued neural network to perform the midstream multi-modal task, adapting the trained glued neural network for a downstream multi-modal task.
Facts
- Company
- Google (Google LLC)
- Official title
- TRAINING VISION LANGUAGE NEURAL NETWORKS WITH COMPONENT REUSE
- Publication number
- US20260311476A1
- Application number
- 19481560
- Filed
- May 10, 2024
- Published
- Oct 8, 2026
- Inventors
- 5
- Claims
- 21
Classified under
G06V 10/82 Physics & computingG06F 40/284 Physics & computingG06N 3/0455 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.