Google patents neural networks that shrink data to save memory
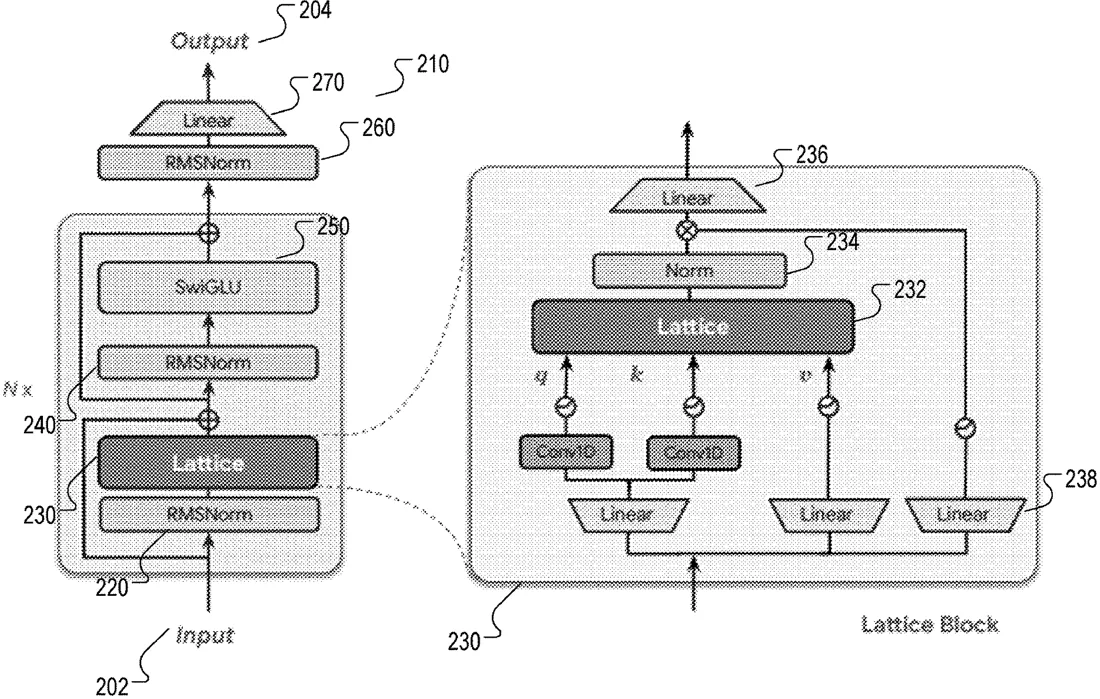
This filing describes a method for building neural networks that use special layers to compress information into a fixed-size memory state. Instead of keeping all previous data, the network updates this small memory block as it generates each new piece of output, allowing it to process long sequences more efficiently.
In the filing’s own words
Systems and methods for generating a network output using a neural network. In particular, the neural network includes one or more compressive attention layers that each “compress” information into a respective fixed size memory state.
What exactly they claim (claim 1)
1. A method performed by one or more computers, the method comprising: obtaining a network input; and processing the network input to generate an output sequence of tokens that comprises a respective output token at each of a plurality of output positions, the processing comprising, for each of the output positions: processing the output token at the preceding output position using a generative neural network conditioned on the network input to generate the output token at the output position, wherein the generative neural network comprises a compressive attention layer, and wherein the processing comprises, for the compressive attention layer: identifying a memory state for the compressive attention layer as of the output position; obtaining a layer input token for the compressive attention layer that is generated from the output token at the preceding output position; generating, from the layer input token for the compressive attention layer, a query vector, a key vector, and a value vector; performing a set of one or more optimization steps on a compression objective using the key vector and the value vector to update the memory state for the compressive attention layer; and after updating the memory state for the compressive attention layer, applying the memory state to the query vector to generate a layer output token for the compressive attention layer.
Facts
- Company
- Google (Google LLC)
- Official title
- GENERATIVE NEURAL NETWORKS WITH COMPRESSIVE ATTENTION LAYERS
- Publication number
- US20260310945A1
- Application number
- 19641299
- Filed
- Apr 7, 2026
- Published
- Oct 8, 2026
- Inventors
- 2
- Claims
- 20
Classified under
G06N 3/0475 Physics & computingG06N 3/0495 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.