Google patents method to fix speaker labels in long audio transcripts
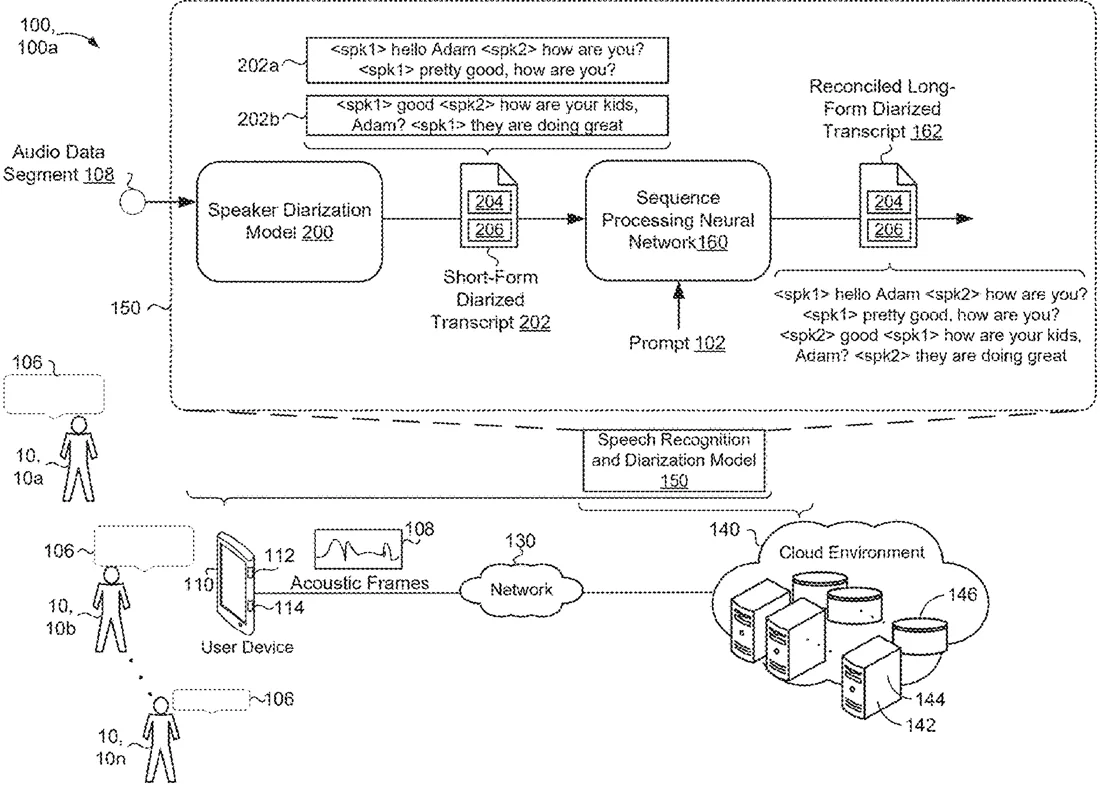
Google describes a system that splits long conversations into smaller chunks to identify who is speaking. It then uses a neural network to combine these chunks into a single transcript, correcting cases where the system confused which speaker was which between segments.
In the filing’s own words
A method includes obtaining a plurality of audio data segments characterizing a conversation between two or more speakers. For each respective audio data segment, the method includes generating a corresponding short-form diarized transcript of a respective portion of the conversation. The corresponding short-form diarized transcript includes a respective sequence of terms and a respective one or more speaker tokens attributing each of the sequence terms to a corresponding speaker identity. The method includes generating a reconciled long-form diarized transcript based on the corresponding short-form diarized transcript generated for each respective audio data segment. A sequence processing neural network generates the reconciled diarized transcript by, for one of the corresponding short-form diarized transcripts, permuting a first speaker token and a second speaker token of the at least one of the corresponding short-form diarized transcripts.
What exactly they claim (claim 1)
1. A computer-implemented method executed on data processing hardware that causes the data processing hardware to perform operations comprising: obtaining a plurality of audio data segments characterizing a conversation between two or more speakers; for each respective audio data segment, generating, using a speaker diarization model, a corresponding short-form diarized transcript of a respective portion of the conversation, the corresponding short-form diarized transcript comprising: a respective sequence of terms; and a respective one or more speaker tokens attributing each of the sequence of terms to a corresponding speaker identity; and generating, using a sequence processing neural network, a reconciled long-form diarized transcript based on the corresponding short-form diarized transcript generated for each respective audio data segment, wherein the sequence processing neural network generates the reconciled diarized transcript by, for one of the corresponding short-form diarized transcripts, permuting a first speaker token and a second speaker token of the one of the corresponding short-form diarized transcripts.
Facts
- Company
- Google (Google LLC)
- Official title
- Reconciling Speaker Permutation In Longform Speaker Diarization with Sequence Processing Neural Networks
- Publication number
- US20260300624A1
- Application number
- 19096629
- Filed
- Mar 31, 2025
- Published
- Oct 1, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06F 40/284 Physics & computingG10L 15/26 Physics & computingG10L 17/04 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.