Google patents method to fine-tune AI search using small adapters
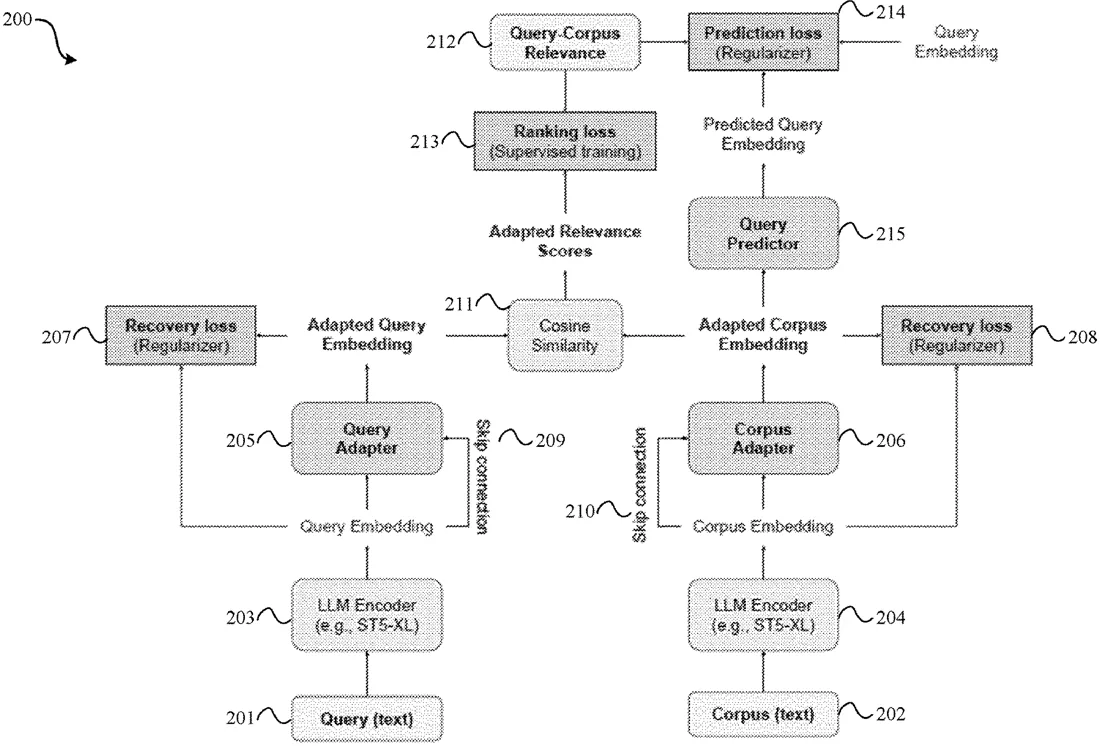
Google describes a technique to improve how large language models find information by using a smaller, trainable component called an IR adapter. This adapter adjusts the data representations of search queries and documents to better match them, while the main AI model stays unchanged. The system learns by comparing the adjusted data to the original search terms to reduce errors.
In the filing’s own words
Aspects of the disclosed technology include techniques and mechanisms for customizing large language models (LLMs) for information retrieval (IR). For a plurality of (query, corpus) pairs, an IR adapter may generate embeddings and adapted embeddings associated with each of the query and the corpus. The IR adapter may analyze the adapted embeddings using a similarity function to determine the similarity between the adapted embeddings. The output of the similarity function may be used to determine a correlation between the query and the corpus, wherein the correlation may be fed back into the IR adapter to train an LLM.
What exactly they claim (claim 1)
1. A computer-implemented method for training an information retrieval (IR) adapter, the method comprising: generating, using a fixed large language model (LLM) encoder, an original query embedding representing a query and an original corpus embedding representing a corpus, wherein parameters of the fixed LLM encoder are fixed; generating, using a trainable IR adapter, an adapted query embedding from the original query embedding and an adapted corpus embedding from the original corpus embedding; predicting, using a query predictor network, a predicted query based on the adapted corpus embedding; calculating a prediction loss using a prediction loss regularizer based on the predicted query and the query; and updating parameters of the trainable IR adapter based at least in part on the prediction loss, wherein the parameters of the fixed LLM encoder remain fixed during said updating.
Facts
- Company
- Google (Google LLC)
- Official title
- Customizing Large Language Models For Information Retrieval
- Publication number
- US20260300357A1
- Application number
- 19703817
- Filed
- Jun 10, 2026
- Published
- Oct 1, 2026
- Inventors
- 2
- Claims
- 20
Classified under
G06F 16/3347 Physics & computingG06F 16/332 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.