Nvidia patents GPU method for faster matrix math using shared memory
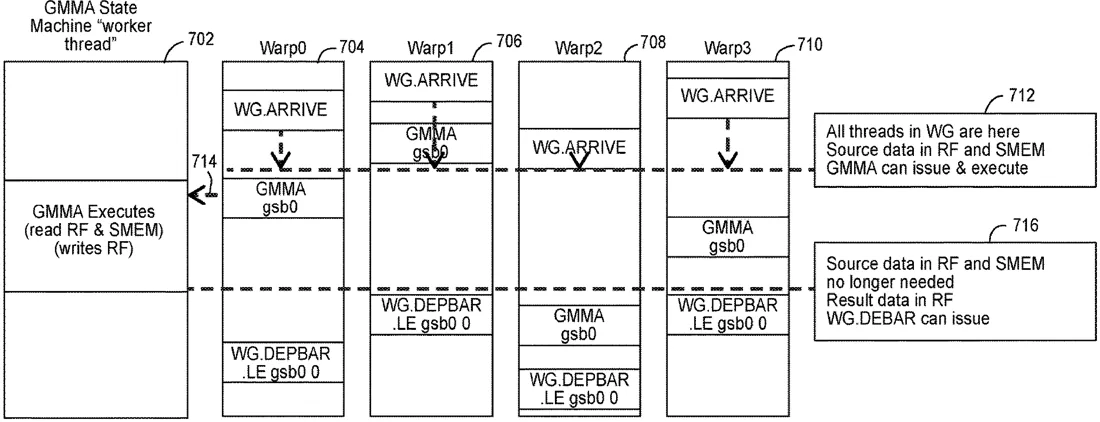
Nvidia describes a way for groups of processing threads to work together on large matrix calculations by sharing their internal storage spaces. A dedicated hardware controller manages this process, allowing the threads to access each other's data without waiting, which helps speed up complex math tasks.
In the filing’s own words
This specification describes techniques for implementing matrix multiply and add (MMA) operations in graphics processing units (GPU)s and other processors. The implementations provide for a plurality of warps of threads to collaborate in generating the result matrix by enabling each thread to share its respective register files to be accessed by the datapaths associated with other threads in the group of warps. A state machine circuit controls a MMA execution among the warps executing on asynchronous computation units. A group MMA (GMMA) instruction provides for a descriptor to be provided as parameter where the descriptor may include information regarding size and formats of input data to be loaded into shared memory and/or the datapath.
What exactly they claim (claim 1)
1. A processor comprising: a plurality of cores, each core comprising a datapath; a work distributor circuit configured to distribute a plurality of warps to the plurality of cores, the plurality of warps including a plurality of threads configured to cooperatively execute a matrix multiply and accumulate (MMA) instruction to determine a result matrix based on input matrices; and a hardware state machine circuit configured to, in response to the MMA instruction and independently of the plurality of threads: (i) load operands of the input matrices to inputs of the respective datapaths; and (ii) control execution of the MMA instruction on the respective datapaths to generate a respective portion of the result matrix at an output of each datapath.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- EFFICIENT MATRIX MULTIPLY AND ADD WITH A GROUP OF WARPS
- Publication number
- US20260299943A1
- Application number
- 19702286
- Filed
- Jun 9, 2026
- Published
- Oct 1, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06F 9/3001 Physics & computingG06F 9/3009 Physics & computingG06F 9/3851 Physics & computingG06F 9/3887 Physics & computingG06F 17/16 Physics & computingG06F 7/5443 Physics & computingMore from Nvidia in Chips & hardware
- Nvidia patents method to skip zero data in neural network math Oct 13, 2026
- Nvidia patents hardware to speed up motion blur in ray tracing Oct 13, 2026
- Nvidia patents method to sync data across split processor chips Sep 17, 2026
- Nvidia patents chip math trick to speed up AI calculations Oct 8, 2026
- Nvidia patents data center cooling that uses cryogenic fluids Oct 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.