OpenAI patents syncing text and audio in AI responses
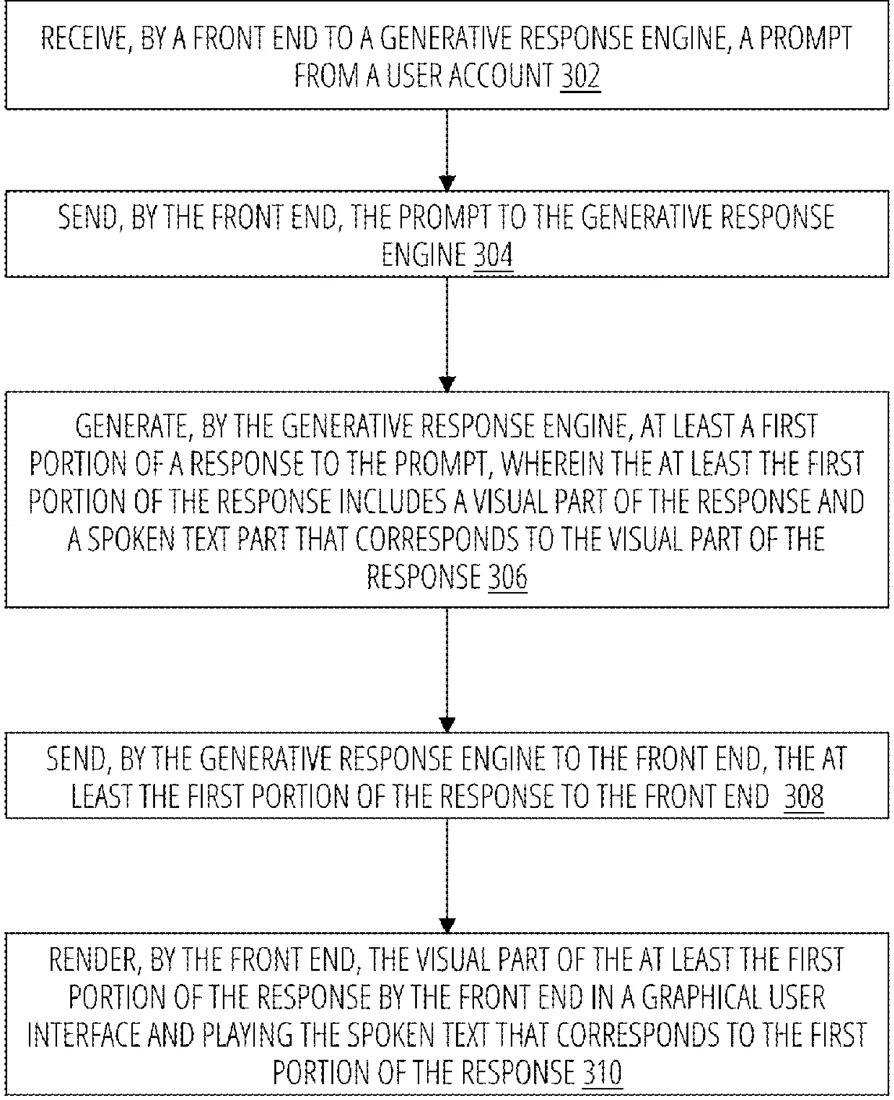
OpenAI has filed a patent for a method that generates both visual text and spoken audio for AI responses simultaneously. The system includes timing data in the text stream to ensure the audio plays in sync with the visual display on the user's screen.
In the filing’s own words
In one aspect, a method includes receiving, by a front end to a generative response engine, a prompt from a user account; generating, by the generative response engine, at least a first portion of a response to the prompt, where the at least the first portion of the response includes a visual part of the response and a spoken text part that corresponds to the visual part of the response; sending, by the generative response engine to the front end, the at least the first portion of the response to the front end; rendering, by the front end, the visual part of the at least the first portion of the response by the front end in a graphical user interface and playing the spoken text that corresponds to the first portion of the response.
What exactly they claim (claim 1)
1. A method comprising: receiving, by a front end to a multi-modal generative response engine, a prompt from a user account; generating, by the multi-modal generative response engine, tokens comprising at least a first portion of a response to the prompt, wherein the at least the first portion of the response includes a visual part and a spoken text part, wherein the visual part comprises a stream of text tokens, and wherein the spoken text part comprises a stream of audio tokens, wherein the spoken text part of the response corresponds to the visual part of the response, and wherein the text tokens comprise instructions for rendering the visual part and offset information generated by the generative response engine and included in the stream of text tokens for synchronizing the visual part and the spoken text part; sending, by the multi-modal generative response engine to the front end, the at least the first portion of the response to the front end; and rendering, by the front end, the visual part of the at least the first portion of the response by the front end in a graphical user interface using the instructions of the text tokens and playing the spoken text that corresponds to the first portion of the response based on the offset information in the stream of text tokens.
Facts
- Company
- OpenAI (OpenAI OpCo, LLC.)
- Official title
- SELECTIVE RENDERING OF GENERATIVE RESPONSE ENGINE OUTPUT
- Publication number
- US20260299744A1
- Application number
- 19240652
- Filed
- Jun 17, 2025
- Published
- Oct 1, 2026
- Inventors
- 1
- Claims
- 21
Classified under
G06F 3/04815 Physics & computingG06F 3/04842 Physics & computingMore from OpenAI in AI & software
- OpenAI patents voice system that detects when you stop talking Sep 22, 2026
- OpenAI patents system to catch AI models cheating on tasks Sep 10, 2026
- OpenAI patents method to check AI thinking for cheating Sep 10, 2026
- OpenAI patents system that turns photos into new AI-generated images Sep 10, 2026
- OpenAI patents AI that answers questions using only your company's secure files Sep 17, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.