Google patents method for choosing better training data for AI models
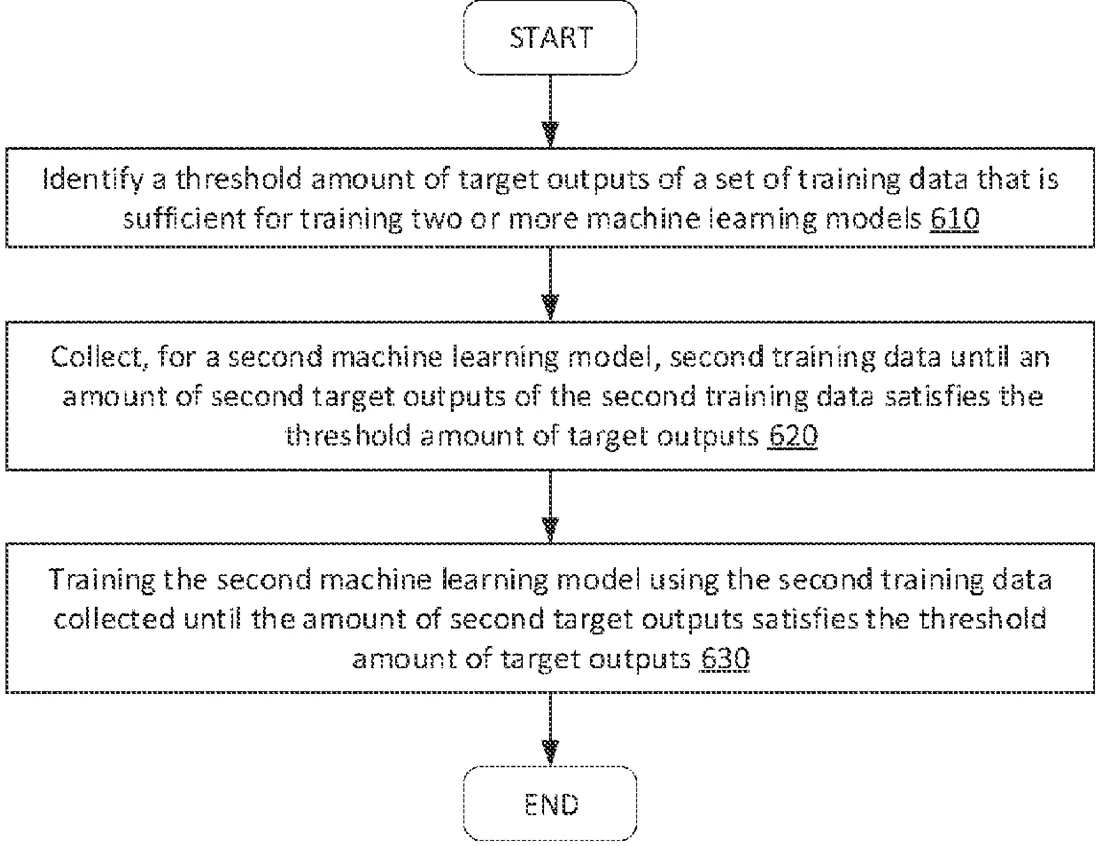
Google describes a system that tests an initial AI model using simulated scenarios to determine how much data is needed for the next version. If the tests pass, the system gathers a larger dataset with more detailed information to train a new, improved model.
In the filing’s own words
Simulation data associated with a simulation test performed with respect to a first set of training data is obtained. Responsive to a determination that the obtained simulation data satisfies one or more criteria, a second set of training data is obtained, where a size of the second set of training data meets or exceeds a size of the first set of training data. A machine learning model is trained using the second set of training data.
What exactly they claim (claim 1)
1. A method comprising: obtaining a first machine learning model trained using a first set of training data, wherein one or more training data items of the first set of training data reflect at least a first attribute of a respective media content item; executing one or more simulation tests using the first machine learning model to generate one or more simulation outputs comprising a performance of the first machine learning model trained using the first set of training data; obtaining a second set of training data to train a second machine learning model, wherein: (i) the second set of training data includes a number of training data items corresponding to a minimum training data set size based on the one or more simulation outputs and a size of the first set of training data, and (ii) the second set of training data comprises the one or more training data items of the first set of training data and one or more additional training data items reflecting one or more second attributes of the respective media content item, the one or more second attributes providing an increased level of granularity with respect to the respective media content item; and causing the second machine learning model to be trained using the second set of training data.
Facts
- Company
- Google (Google LLC)
- Official title
- System and methods for machine learning training data selection
- Patent number
- US12762479B2
- Application number
- 18444360
- Filed
- Feb 16, 2024
- Granted
- Oct 13, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06N 20/00 Physics & computingG06F 11/3668 Physics & computingG06F 18/214 Physics & computingG06N 20/20 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.