Google patents method to create training data using language models
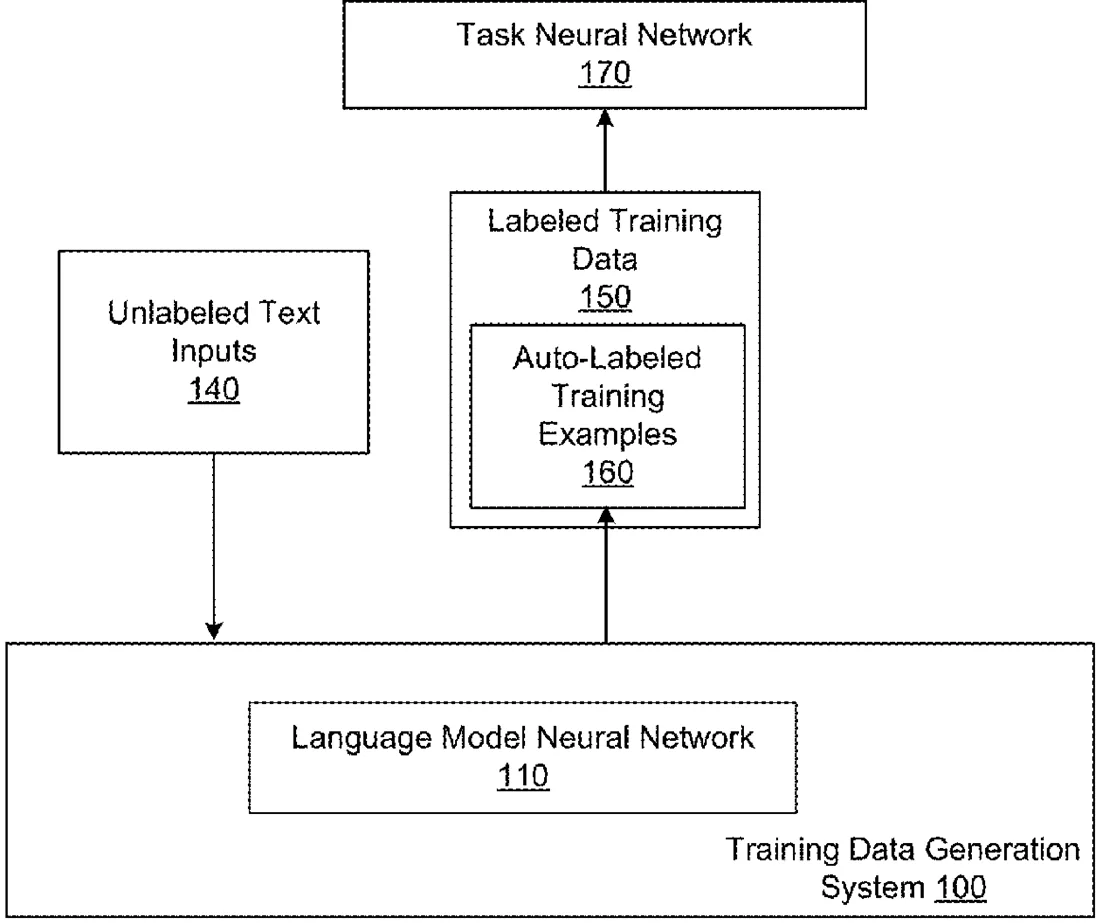
This patent describes a way to automatically create labeled data for training smaller AI models. It uses a large, pre-trained language model to generate new text examples based on specific categories, which are then used to teach a separate model how to classify text.
In the filing’s own words
Methods, systems, and apparatus, including computer programs encoded on computer storage media, for generating labeled training data using a pre-trained language model neural network. In particular, the language model neural network can generate the text input in a new labeled training example from an input sequence that includes (i) one or more context inputs and (ii) a text label that identifies the ground truth category for the new labeled training example.
What exactly they claim (claim 1)
1. A method performed by one or more computers, the method comprising: obtaining a plurality of unlabeled text inputs for a text classification task, each unlabeled text input comprising a respective sequence of text tokens, and the text classification task requiring classifying input text inputs into a plurality of categories; generating a plurality of auto-labeled training examples for the text classification task, wherein each auto-labeled training example comprises a respective text input and identifies a respective target category from the plurality of categories for the respective text input, the generating comprising: selecting, as context text inputs, one or more of the unlabeled text inputs; generating an input sequence of text tokens that includes (i) the one or more context text inputs and (ii) a text label that identifies a respective one of the plurality of categories; processing, using a pre-trained language model neural network, the input sequence to generate an output sequence of text token; and generating an auto-labeled training example that (i) includes, as the respective text input in the training example, the output sequence generated by the pre-trained language model neural network by processing the input sequence that includes the text label; and (ii) identifies, as the respective target category for the output sequence, the respective category identified by the text label in the input sequence that was provided as input to the pre-trained language model neural network; and training a task neural network to perform the text classification task on labeled training data that comprises the auto-labeled training examples, wherein the training comprises training the task neural network to predict, for each auto-labeled training example and by processing the output sequence generated as output by the pre-trained language model neural network, the respective category identified by the text label provided as input to the pre-trained language model neural network.
Facts
- Company
- Google (Google LLC)
- Official title
- Generating labeled training data using a pre-trained language model neural network
- Patent number
- US12762399B2
- Application number
- 18082934
- Filed
- Dec 16, 2022
- Granted
- Oct 13, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06N 3/08 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.