Google patents method to share AI models while keeping user data private
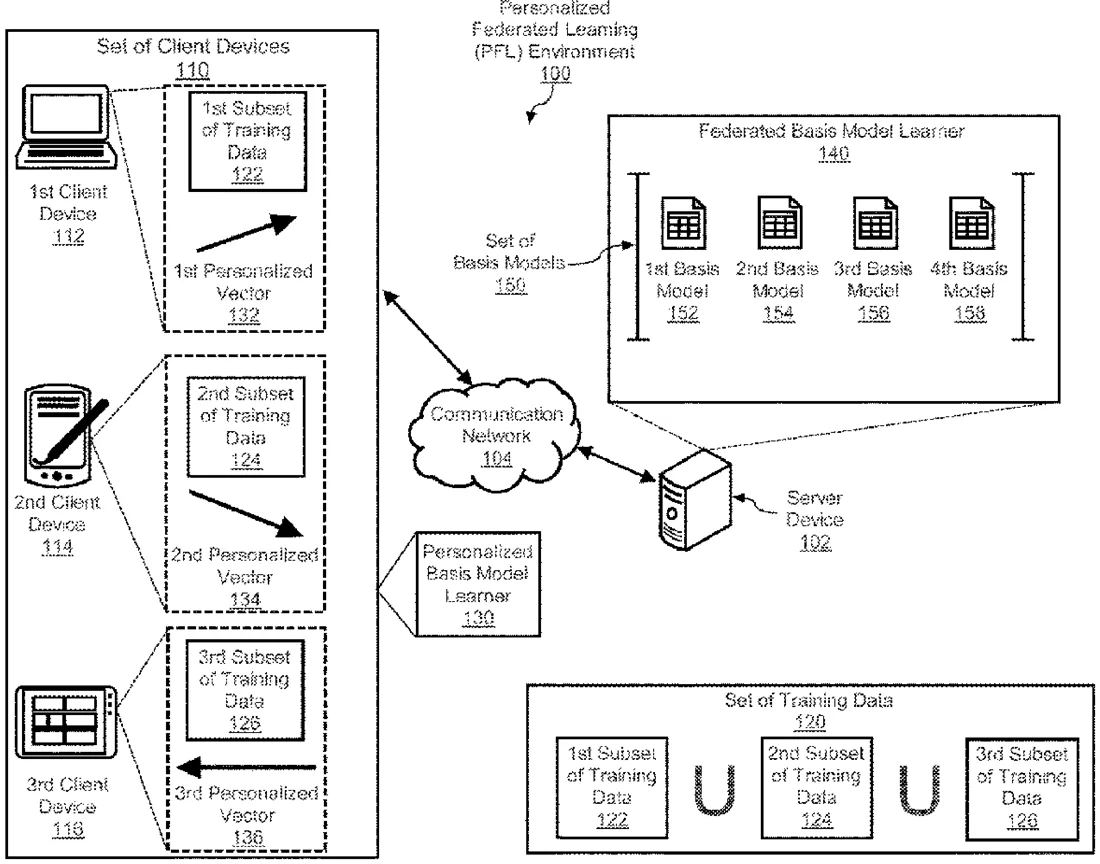
Google describes a system where a server sends untrained AI models to many devices, which train them using only local data. The server then combines these results into shared 'basis models' that each device mixes in a unique way to create a personalized AI without sharing raw data.
In the filing’s own words
The embodiments are directed towards providing personalized federated learning (PFL) models via sharable federated basis models. A model architecture and learning algorithm for PFL models is disclosed. The embodiments learn a set of basis models, which can be combined layer by layer to form a personalized model for each client using specifically learned combination coefficients. The set of basis models are shared with each client of a set of the clients. Thus, the set of basis models is common to each client of the set of clients. However, each client may generate a unique PFL based on their specifically learned combination coefficients. The unique combination of coefficients for each client may be encoded in a separate personalized vector for each of the clients.
What exactly they claim (claim 1)
1. A method implemented by a server device, the method comprising: providing, each client device of a set of client devices, a set of untrained models; causing, each client device of the set of client devices, to generate a separate set of trained models based on the set of untrained models, wherein each client device iteratively trains the set of untrained models based on a separate subset of a set of training data that is located locally on the client device such that each subset of the set of training data is inaccessible by the server device and each subset of the set of training data is inaccessible by the client device except for the subset of training data that is located locally on the client device; receiving, at the server device, a separate set of trained models from each client device; generating, at the server device, a set of basis models based on a combination of the separate set of trained models received from each of the client devices; providing, each client of the set of clients, the set of basis models; and causing, each client device of the set of client devices, to generate a personalized model based on a separate linear combination of the basis models of the set of basis models.
Facts
- Company
- Google (Google LLC)
- Official title
- Personalized federated learning via sharable basis models
- Patent number
- US12748982B2
- Application number
- 18474934
- Filed
- Sep 26, 2023
- Granted
- Sep 29, 2026
- Inventors
- 6
- Claims
- 20
Classified under
G06N 3/098 Physics & computingMore from Google in AI & software
- Google patents video search that answers questions using AI descriptions Sep 15, 2026
- Google patents photo tool that removes people and their gear Sep 15, 2026
- Google patents AI that writes live meeting notes and summaries Sep 15, 2026
- Google patents AI tool that turns messy emergency notes into clear messages Sep 3, 2026
- Google patents AI that clicks through apps to finish tasks for you Sep 24, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.