Nvidia patents method to train 3D scene models without manual labels
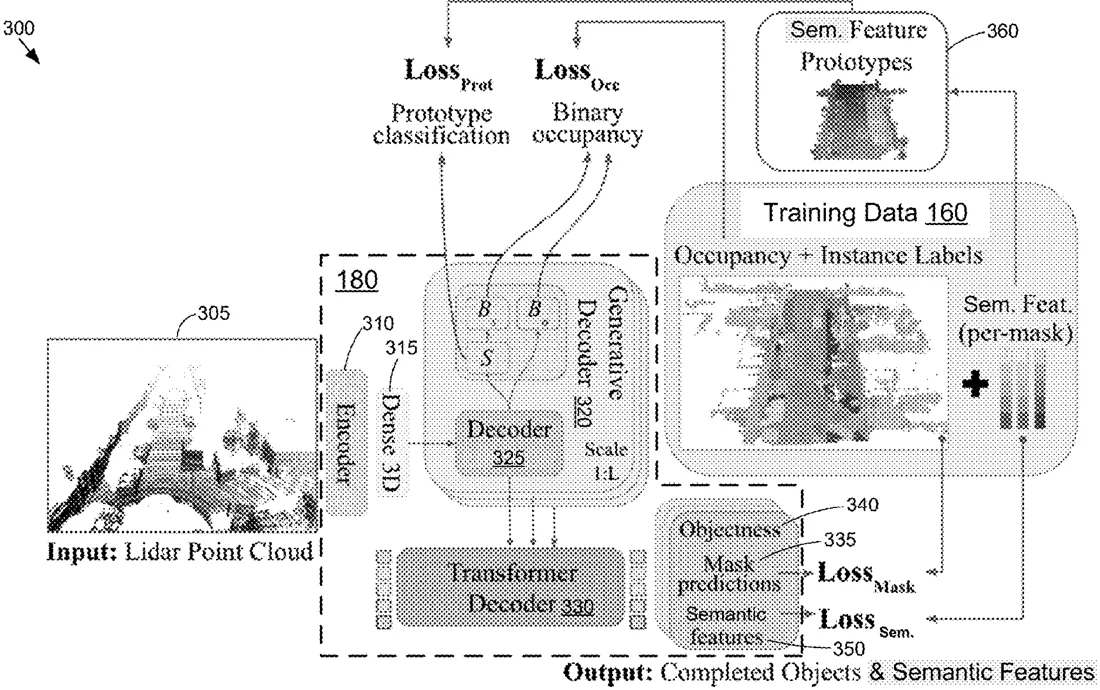
Nvidia describes a technique for training neural networks to understand 3D scenes using LiDAR data. Instead of requiring humans to label every object, the system groups similar objects into clusters to create automatic training targets.
In the filing’s own words
To facilitate training on unlabeled data, class prototypes or pseudo-classes may be used in lieu of class labels. For example, the mined pseudo-labels may include a 3D mask and semantic embedding for each object instance in the scene, and the semantic embeddings for all object instances in a scene may be clustered into prototypes or pseudo-classes representing semantic clusters of inferred classes. Each voxel may be assigned an identifier for the cluster it is in, and a prototype head may be used to predict which prototypes or pseudo-class each voxel is in. This way, the mined prototypes or pseudo-classes may be used as supervision during training, for example, jointly with other signals such as occupancy loss, mask loss (e.g., matching predicted masks to pseudo-labeled masks using Hungarian matching), and/or feature alignment loss (e.g., aligning predicted instance features with target semantic embeddings).
What exactly they claim (claim 1)
1. A system comprising one or more processors to: execute one or more iterations of training a neural network, wherein an iteration of the one or more iterations comprises: generating, based at least on applying a representation of LiDAR data to a neural network, one or more predicted three-dimensional (3D) masks representing one or more detected object instances and one or more semantic embeddings of the one or more detected object instances; identifying, from a training dataset, one or more reconstructed 3D masks that correspond to the one or more predicted 3D masks; and updating one or more parameters of the neural network based at least on comparing the one or more semantic embeddings with one or more automatically labeled semantic embeddings associated with the one or more reconstructed 3D masks in the training dataset.
Facts
- Company
- Nvidia (NVIDIA CORPORATION)
- Official title
- TRAINING TECHNIQUES FOR PANOPTIC SCENE COMPLETION
- Publication number
- US20260330644A1
- Application number
- 19643480
- Filed
- Apr 9, 2026
- Published
- Oct 22, 2026
- Inventors
- 7
- Claims
- 20
Classified under
G06T 7/12 Physics & computingG06N 3/08 Physics & computingG06T 7/20 Physics & computingG06V 10/82 Physics & computingG06V 20/70 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.