Nvidia patents method to shrink hybrid AI models
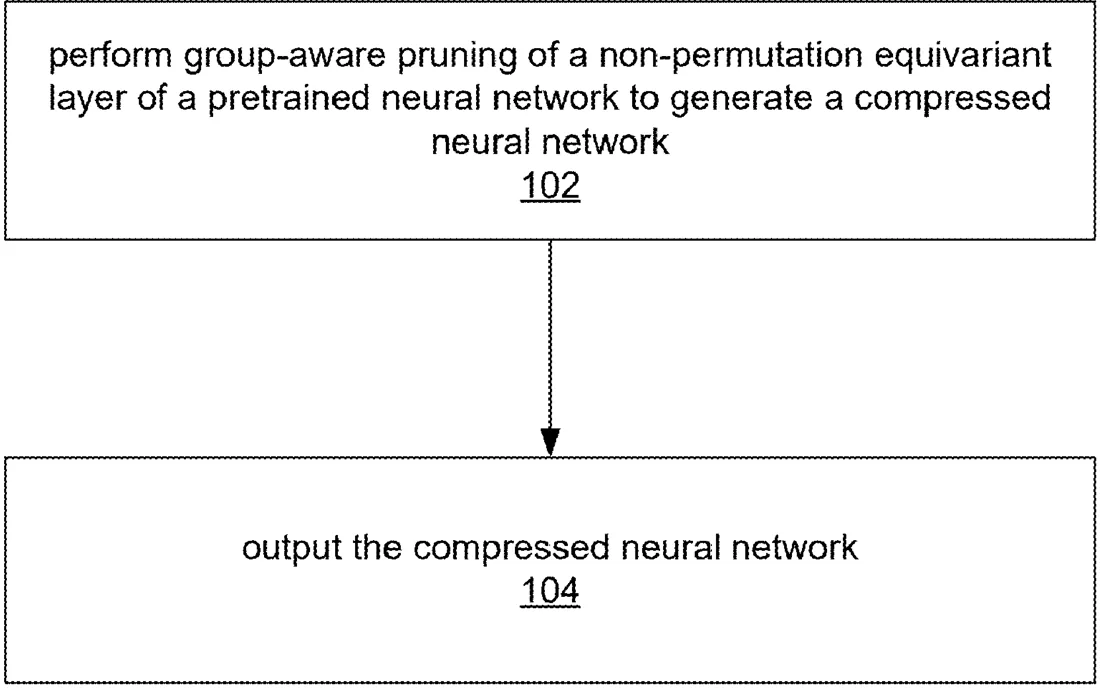
Nvidia describes a technique to make hybrid AI models smaller by removing unnecessary parts of their internal structure. The method specifically protects the unique components of these models that handle text sequences, ensuring they still work well after being reduced in size.
In the filing’s own words
Recent advances in language modeling have led to the development of hybrid architectures that combine Transformer layers with State Space Models (SSMs). These hybrid models leverage the complementary strengths of both approaches: Transformers excel at capturing global dependencies through self-attention mechanisms, while SSMs provide efficient sequence processing with O(N) scaling during training and O(1) cache size during inference. Despite their improved efficiency, many hybrid language models, including hybrid large language models (LLMs), remain incredibly large, often spanning billions of parameters. This motivates the need for efficiently creating smaller (i.e. compressing) hybrid language models suitable for deployment in various resource-constrained environments. The present disclosure provides a group-aware pruning strategy for hybrid language models and pretrained neural networks having non-permutation equivariant layers, which can preserve the structural integrity of SSM blocks and their sequence modeling capabilities to achieve improved accuracy and inference speed compared to traditional approaches.
What exactly they claim (claim 1)
1. A method, comprising: at a device: performing group-aware pruning of a non-permutation equivariant layer of a pretrained neural network to generate a compressed neural network; and outputting the compressed neural network.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- HYBRID LANGUAGE MODEL COMPRESSION THROUGH GROUP-AWARE PRUNING
- Publication number
- US20260330225A1
- Application number
- 19322454
- Filed
- Sep 8, 2025
- Published
- Oct 22, 2026
- Inventors
- 14
- Claims
- 32
Classified under
G06N 3/082 Physics & computingG06N 3/048 Physics & computingG06N 3/0495 Physics & computingG06N 3/096 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.