Nvidia patents system that uses AI to organize and format content data
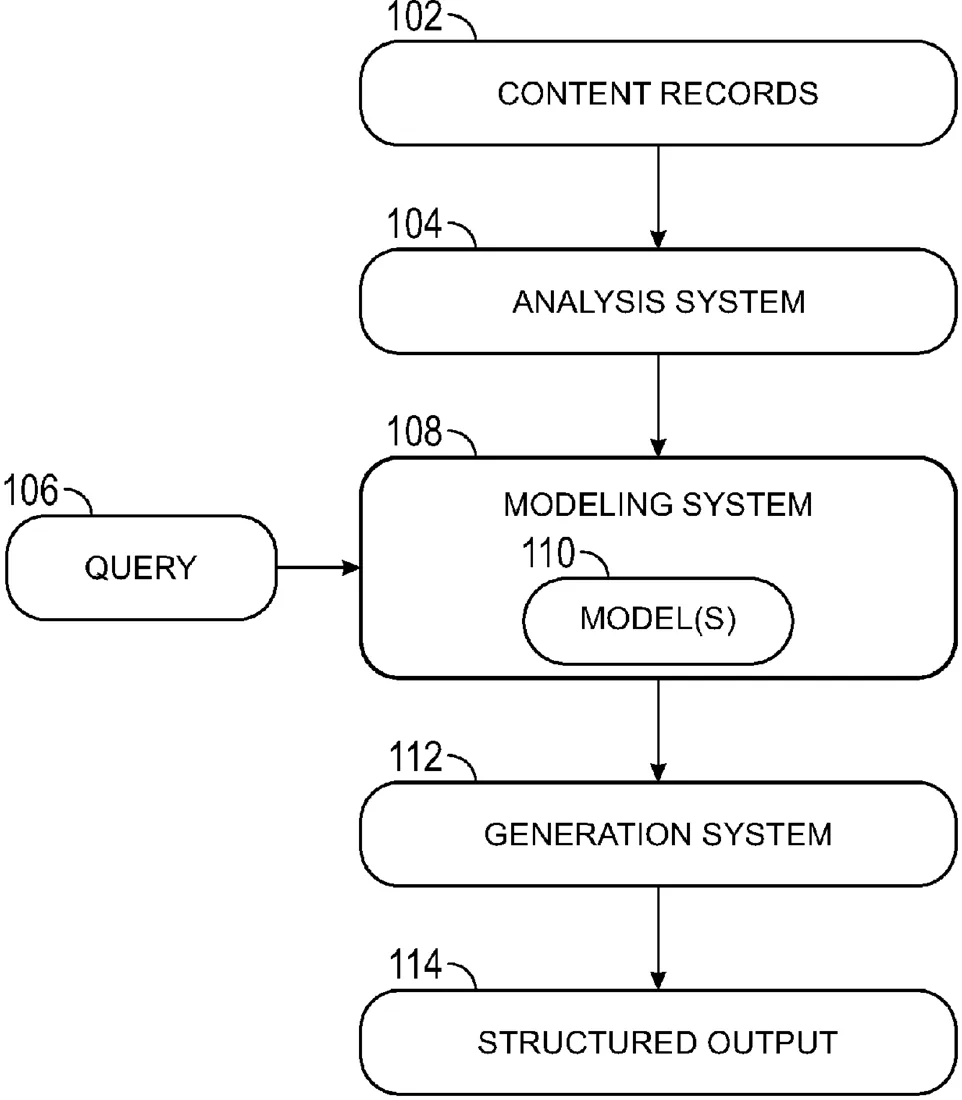
Nvidia describes a system that pulls content records from data sources and uses a language model to modify that content based on specific categories. The system then arranges the modified content and its metadata into a structured format using a predefined template for display.
In the filing’s own words
Various examples, systems, and methods are disclosed relating to a content curation pipeline. A first computing system obtain, from at least one data source, a plurality of content records corresponding with at least one content source of the at least one data source. The first computing system determine a subset of a plurality of embeddings corresponding to at least one category. The first computing system apply the subset of the plurality of embeddings as input to at least one language model (LM) to cause the at least one LM to generate, using a template, at least one structured output comprising a plurality of modified content and corresponding metadata. The first computing system provide, via an interface, the at least one structured output.
What exactly they claim (claim 1)
1. A system, comprising: one or more processors to: obtain, from at least one data source, a plurality of content records corresponding with at least one content source of the at least one data source; determine a subset of a plurality of embeddings corresponding to at least one category, wherein determining the subset of the plurality of embeddings is based at least on a ranking of the plurality of embeddings organized according to the at least one category; apply the subset of the plurality of embeddings as input to at least one language model (LM) to cause the at least one LM to generate a plurality of modified content and corresponding metadata; generate, using the plurality of modified content and the corresponding metadata, at least one output based at least on a template; and provide, via an interface, the at least one output.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- CONTENT MODELING AND STRUCTURED OUTPUT GENERATION
- Publication number
- US20260320096A1
- Application number
- 19179103
- Filed
- Apr 15, 2025
- Published
- Oct 15, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06F 16/334 Physics & computingG06F 16/335 Physics & computingG06F 16/345 Physics & computingG06F 16/353 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.