Nvidia patents system to answer questions across multiple databases
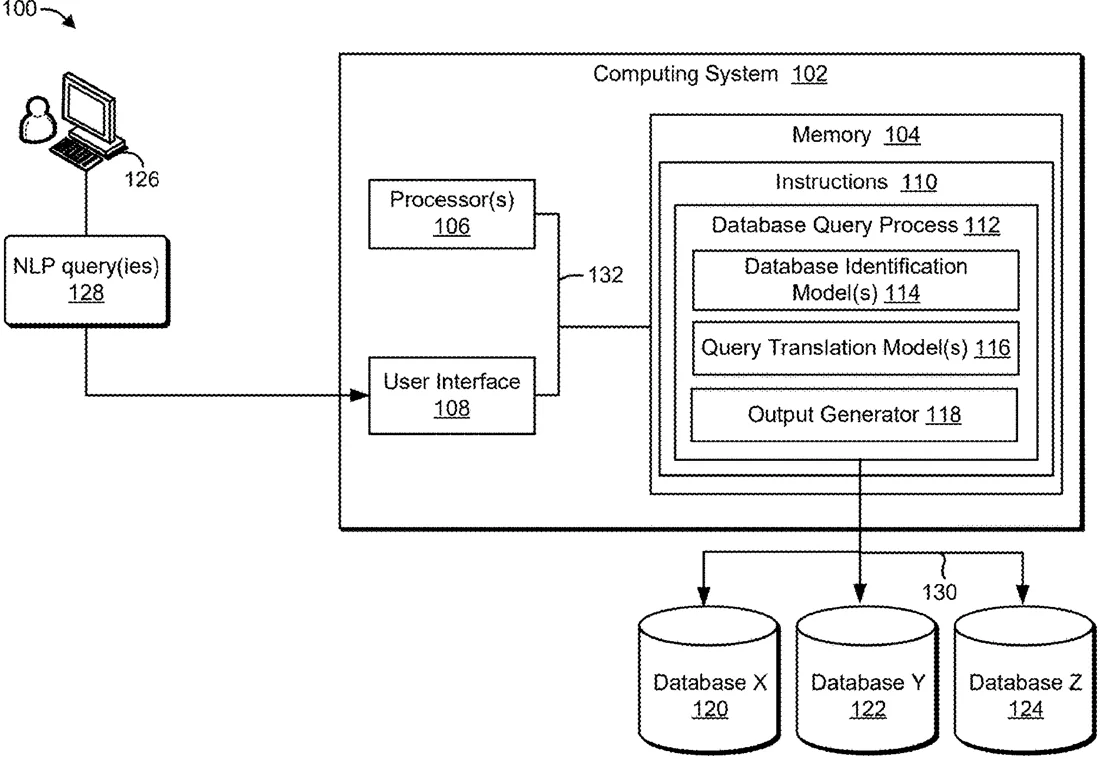
Nvidia describes a system that uses machine learning to answer questions written in plain English by searching several different databases at once. The software breaks the question into smaller parts, translates them into the specific language each database understands, and then combines the answers into a single, easy-to-read table.
In the filing’s own words
In some examples, apparatuses, systems, methods, processors, and techniques are described that use one or more machine learning models to perform natural language queries involving two or more data sources (e.g., databases, data lakes, etc.). For example, two or more data sources may be identified as storing data potentially responsive to a natural language query (e.g., a prompt), and two or more database sub-queries are obtained based at least on the natural language query. The database sub-queries are used to obtain results from the identified data sources, and the obtained data is mapped to a data structure, such as a table, to present the results from the data sources correlated based on the natural language query.
What exactly they claim (claim 1)
1. A system comprising one or more processors to at least: identify, using one or more neural networks and based at least on a natural language query, two or more databases of two or more different database types: obtain, using the one or more neural networks and based at least on the natural language query, two or more sub-queries; translate, using the one or more neural networks, the two or more sub-queries into two or more database queries according to respective input formats of the two or more databases; obtain results from the two or more databases based at least on executing the two or more database queries with respect to the two or more databases; merge the obtained results into a unified output based at least on one or more relationships between the two or more sub-queries determined based at least on the natural language query; and cause at least one of presentation or storage of the unified output.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- NATURAL LANGUAGE MULTI-DATABASE QUERY PROCESSING
- Publication number
- US20260320036A1
- Application number
- 19176037
- Filed
- Apr 10, 2025
- Published
- Oct 15, 2026
- Inventors
- 3
- Claims
- 20
Classified under
G06F 16/243 Physics & computingG06F 16/24522 Physics & computingG06F 16/248 Physics & computingG06F 16/285 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.