Nvidia patents method to auto-label game images for AI training
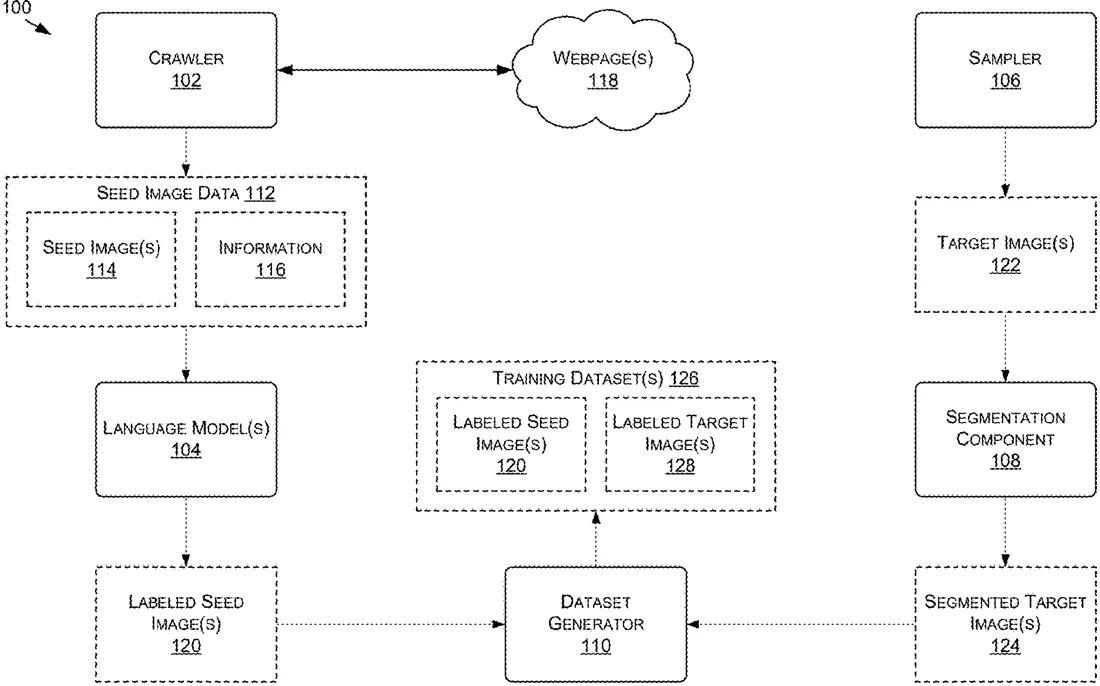
Nvidia describes a system that automatically creates training data for computer vision models by scanning web pages for images related to interactive applications, such as video games. It uses a multimodal language model to analyze these images and their associated text to assign accurate labels, which are then used to find and categorize additional similar images to expand the dataset.
In the filing’s own words
In various examples, datasets for training computer vision and/or other artificial intelligence (AI) models may be automatically generated using AI-based techniques. For instance, the systems and methods of the present disclosure may crawl network resources (e.g., webpages) that include information associated with an interactive application (e.g., a wiki page for a gaming application) to obtain “seed” images depicting objects from the interactive application, as well as information (e.g., metadata) corresponding to the seed images. In some examples, a multimodal language model may be used to process the seed images and corresponding information. Based on the processing, the systems and methods may assign one or more labels to the seed images. The labeled seed images may then be used to expand the training dataset by processing and identifying additional images that depict similar objects to those in the labeled seed images.
What exactly they claim (claim 1)
1. A method comprising: obtaining, based at least on analyzing webpage code corresponding to one or more webpages associated with an interactive application, at least: image data representing one or more first images depicting one or more first objects of the interactive application; and text data representing information associated with the one or more first images; determining, using one or more multimodal language models to process at least the image data and the text data, one or more labels for the one or more first images, the one or more labels indicative of at least one or more classifications of the one or more first objects depicted in the one or more first images; and generating, using at least the one or more first images and the one or more labels, one or more training datasets including one or more second images depicting one or more second objects having the one or more classifications.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- AUTOMATIC DATASET GENERATION FOR TRAINING COMPUTER VISION SYSTEMS AND APPLICATIONS
- Publication number
- US20260301378A1
- Application number
- 19091436
- Filed
- Mar 26, 2025
- Published
- Oct 1, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06V 10/774 Physics & computingG06V 10/26 Physics & computingG06V 10/761 Physics & computingG06V 10/764 Physics & computingG06V 30/10 Physics & computingG06V 30/413 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.