Amazon patents system to keep AI training running when servers fail
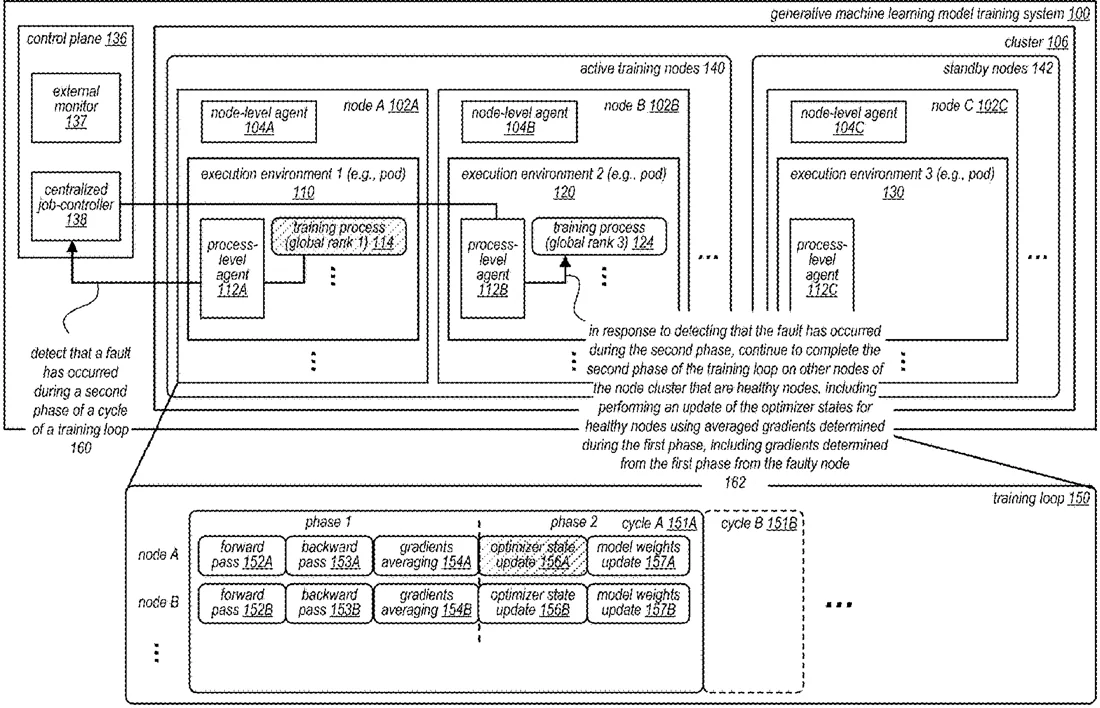
Amazon describes a system for training large AI models on clusters of computers that can handle hardware failures. If a server crashes during a specific part of the training loop, the system lets other healthy servers finish the work using data already calculated, then swaps in a backup server to continue the process.
In the filing’s own words
A generative machine learning model training system manages distributed training processes across a cluster of nodes, wherein each node executes tasks corresponding to discrete cycles of a training loop. Each cycle comprises a first phase including a forward pass, backward pass, and gradient averaging and a second phase that updates optimizer states and model weights based on the averaged gradients. Subsequent to detecting a fault occurring during the second phase at a given node, the generative machine learning model training system allows the healthy nodes to complete the second phase using gradients previously averaged during the first phase. The generative machine learning model training system sends updated optimizer states and model weights from a healthy node to initialize a standby node and proceed to perform another cycle using the standby node and the healthy nodes.
What exactly they claim (claim 1)
1. A system, comprising: one or more computing devices configured to: train, using a node cluster managed by a generative machine learning model training system, a given generative machine learning model with a training job, wherein the node cluster perform training processes of the training job; detect a fault for one or more training processes performed on a given node of the node cluster; determine whether the fault has occurred during a first phase or a second phase of a cycle of a training loop for the training job, wherein the cycle comprises the first phase and the second phase, and wherein the first phase comprises: a forward pass, a backward pass, and an averaging of gradients across the node cluster, and the second phase comprises: an update of an optimizer state using the averaged gradients, and an update of weights for the given generative machine learning model using the updated optimizer state; in response to a determination that the fault has occurred during the second phase on the given node, continue to complete the second phase of the training loop on other nodes of the node cluster that are healthy nodes, wherein to continue to complete the second phase on the healthy nodes, the one or more computing devices are configured to: perform the update of the optimizer states for the healthy nodes using the averaged gradients determined during the first phase, including for the given node; and send, from a selected one of the healthy nodes to a standby node, the updated optimizer state and the updated weights.
Facts
- Company
- Amazon (Amazon Technologies, Inc.)
- Official title
- GENERATIVE MACHINE LEARNING MODEL TRAINING SYSTEM
- Publication number
- US20260300819A1
- Application number
- 19096475
- Filed
- Mar 31, 2025
- Published
- Oct 1, 2026
- Inventors
- 10
- Claims
- 20
Classified under
G06N 20/00 Physics & computingG06F 11/3612 Physics & computingMore from Amazon in AI & software
- Amazon patents system that cites sources for AI answers Sep 29, 2026
- Amazon patents tech to swap words in movies using actor's voice Sep 8, 2026
- Amazon patents ML tool to add graphics to live sports from moving cameras Sep 15, 2026
- Amazon patents shopping assistant that remembers your search filters Oct 6, 2026
- Amazon patents system where AI agents split tasks and talk to each other Oct 20, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.