Amazon patents method to shrink neural network weights for faster chips
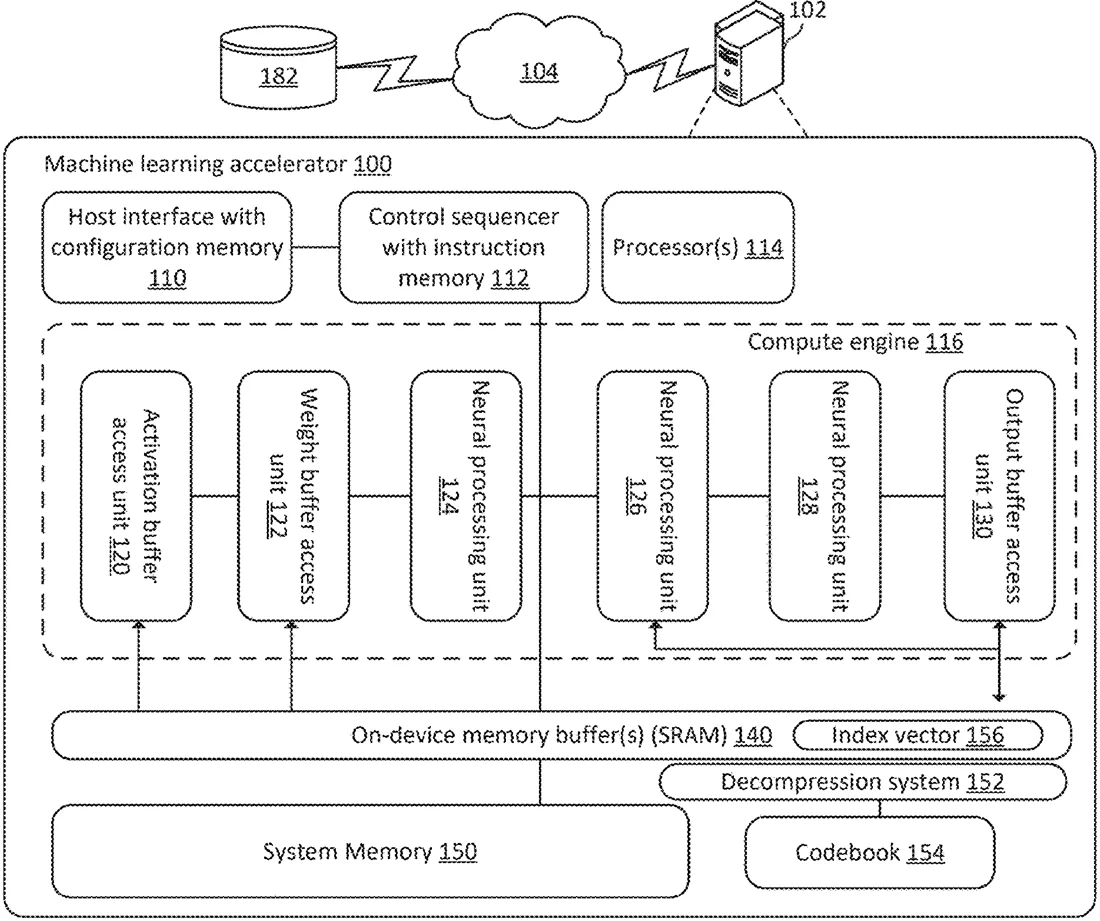
Amazon describes a technique for compressing the mathematical weights used in artificial intelligence models. Instead of storing every number directly, the system saves small codes that are looked up in a dictionary to reconstruct the original values when needed. This allows the hardware to process data using less memory space.
In the filing’s own words
Devices and techniques are generally described for vectorwise weight quantization for neural networks. In some examples, a first index vector stored in volatile memory may be determined for a first layer of a neural network. First code data may be determined by performing a lookup using the first index vector as an index into a codebook. A first weight vector may be determined by decoding the first code data using a first decoding algorithm. Each element of the first weight vector may represent a respective weight for the first layer of the neural network. An output for the first layer of the neural network may be computed using the weights of the first weight vector.
What exactly they claim (claim 1)
1. A system comprising: a neural network accelerator apparatus comprising: one or more processors; an arithmetic logic unit (ALU); a compute engine; an input selector; and one or more computer readable media comprising static random access memory (SRAM), the one or more computer readable media storing processor executable instructions which, when executed using the one or more processors, perform operations comprising: determining, for a first layer of a neural network, a first index vector stored in the SRAM, wherein a first element of the first index vector comprises a first hexadecimal value and a second element of the first index vector comprises a second hexadecimal value; determining first code data by performing a lookup using the first index vector as an index into a codebook; determining, by the input selector, a first decoding algorithm associated with the first index vector; programming, by the input selector, the ALU to decode the first code data using the first decoding algorithm; generating, by the ALU, a first full-precision weight vector by decoding the first code data, wherein each element of the first full-precision weight vector represents a respective full-precision weight for the first layer of the neural network; and computing, by the compute engine, an output for the first layer of the neural network using the full-precision weights of the first full-precision weight vector.
Facts
- Company
- Amazon (Amazon Technologies, Inc.)
- Official title
- WEIGHT VECTOR QUANTIZATION FOR NEURAL NETWORKS
- Publication number
- US20260300680A1
- Application number
- 19096250
- Filed
- Mar 31, 2025
- Published
- Oct 1, 2026
- Inventors
- 5
- Claims
- 20
Classified under
G06N 3/04 Physics & computingMore from Amazon in AI & software
- Amazon patents system that cites sources for AI answers Sep 29, 2026
- Amazon patents tech to swap words in movies using actor's voice Sep 8, 2026
- Amazon patents ML tool to add graphics to live sports from moving cameras Sep 15, 2026
- Amazon patents shopping assistant that remembers your search filters Oct 6, 2026
- Amazon patents system where AI agents split tasks and talk to each other Oct 20, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.