Amazon patents method to stop AI from copying source documents
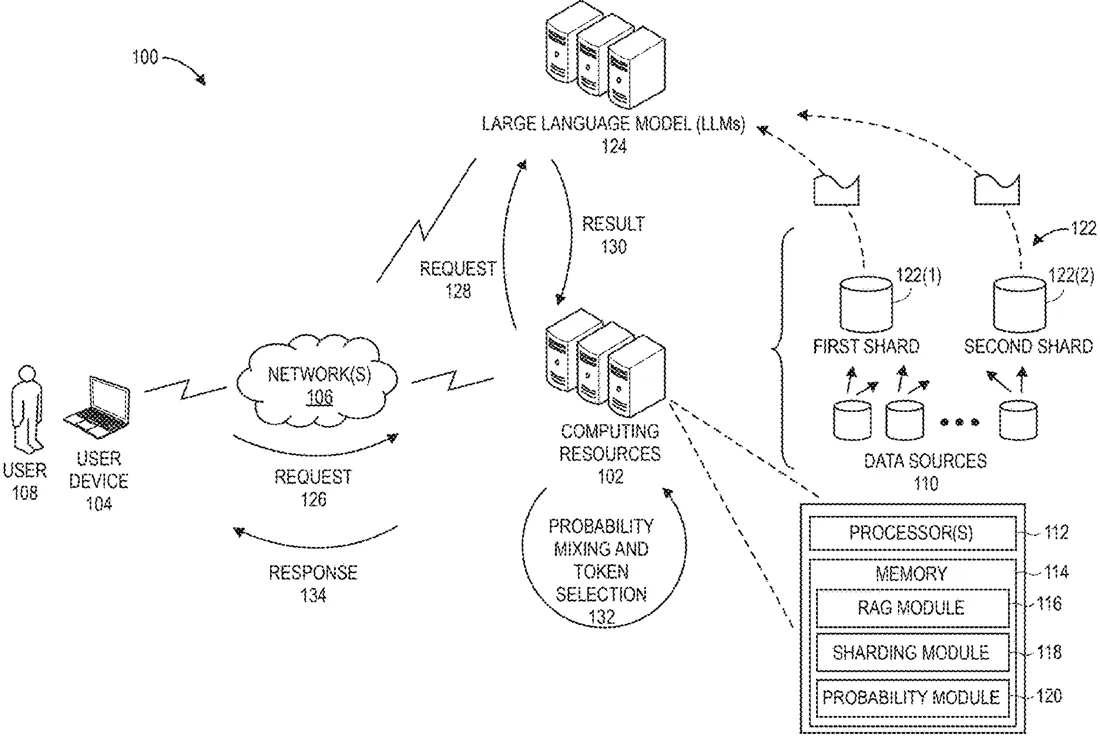
Amazon describes a system that splits sensitive data into separate pieces before feeding it to an AI model. The model processes each piece individually to predict the next word, then combines the results to ensure the final answer does not closely mimic the original source text.
In the filing’s own words
Described are systems and processes for providing copy protection in results provided by a Large Language Model (LLM) that uses Retrieval-Augmented Generation (RAG) of data sources. The data sources may be sharded into a first shard and a second shard. A first query may be sent to the LLM using RAG with the first shard to determine a token with a first probability. A second query may be sent to the LLM using RAG with the second shard to determine the token with a second probability. A combined probability may be determined for the token based on the first probability and the second probability. The combined probability may be used to select the token. These systems and processes reduce a risk that the LLM is too closely tied to any specific data and thus replicates an extended amount of that data.
What exactly they claim (claim 1)
1. A system, comprising: one or more processors; and memory storing program instructions that, when executed by the one or more processors, cause the one or more processors to at least: determine that a data source includes sensitive data; shard the data source into at least a first shard and a second shard; receive a request for generative text to be provided in part by a large language model (LLM) implemented with retrieval-augmented generation (RAG) and having access to at least the first shard and the second shard; send a first query to the LLM implementing the RAG with the first shard to obtain first probabilities associated with first tokens used to determine a next token in the generative text; send a second query to the LLM implementing the RAG with the second shard to obtain second probabilities associated with second tokens used to determine the next token in the generative text; determine combined probabilities based in part on at least one of the first probabilities and second probabilities obtained from the LLM for tokens included in the first tokens and the second tokens; select the next token for the generative text from the tokens based at least in part on the combined probabilities; and generate, in response to the request, the generative text that includes a word associated with the next token.
Facts
- Company
- Amazon (Amazon Technologies, Inc.)
- Official title
- COPY SUPPRESSION FOR RETRIEVAL-AUGMENTED GENERATION OUTPUTS
- Publication number
- US20260300623A1
- Application number
- 19092781
- Filed
- Mar 27, 2025
- Published
- Oct 1, 2026
- Inventors
- 2
- Claims
- 20
Classified under
G06F 40/284 Physics & computingG06F 16/313 Physics & computingMore from Amazon in AI & software
- Amazon patents system that cites sources for AI answers Sep 29, 2026
- Amazon patents tech to swap words in movies using actor's voice Sep 8, 2026
- Amazon patents ML tool to add graphics to live sports from moving cameras Sep 15, 2026
- Amazon patents shopping assistant that remembers your search filters Oct 6, 2026
- Amazon patents system where AI agents split tasks and talk to each other Oct 20, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.