Google patents speech system that matches voice style to conversation flow
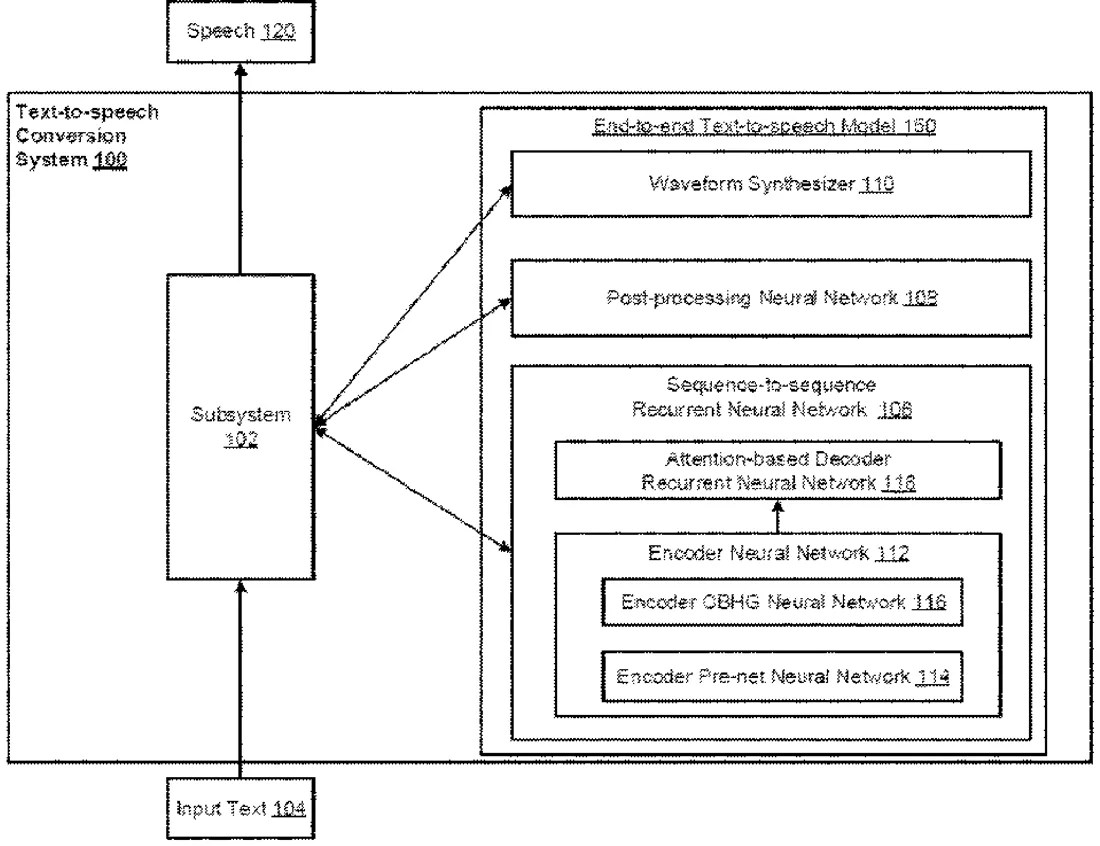
This patent describes a system that makes computer-generated speech sound more natural by adjusting its tone based on the conversation history. It uses a network to analyze previous spoken questions and creates a 'style guide' for the current answer, ensuring the voice changes appropriately as the dialogue progresses.
In the filing’s own words
A system for generating an output audio signal includes a context encoder, a text-prediction network, and a text-to-speech (TTS) model. The context encoder is configured to receive one or more context features associated with current input text and process the one or more context features to generate a context embedding associated with the current input text. The text-prediction network is configured to process the current input text and the context embedding to predict, as output, a style embedding for the current input text. The style embedding specifies a specific prosody and/or style for synthesizing the current input text into expressive speech. The TTS model is configured to process the current input text and the style embedding to generate an output audio signal of expressive speech of the current input text. The output audio signal has the specific prosody and/or style specified by the style embedding.
What exactly they claim (claim 1)
1. A computer-implemented method executed on data processing hardware that causes the data processing hardware to perform operations comprising: receiving, from a query-response system, current input text to be synthesized into expressive speech by a text-to-speech (TTS) model, the current input text corresponding to a response to a current spoken query in a sequence of spoken queries received at the query-response system, each spoken query in the sequence of spoken queries spoken by a user; obtaining one or more context features associated with the current input text, the one or more context features comprising audio features associated with one or more spoken queries preceding the current spoken query in the sequence of spoken queries received at the query-response system; predicting, using a text-prediction network, a style embedding for the current input text based on the one or more context features associated with the current input text, the style embedding specifying a specific style for synthesizing the current input text into express speech; and generating, using the TTS model, an output audio signal of expressive speech of the current input text by processing the style embedding and the current input text, the output audio signal having the specific style specified by the style embedding.
Facts
- Company
- Google (Google LLC)
- Official title
- Controlling expressivity in end-to-end speech synthesis systems
- Patent number
- US12770609B2
- Application number
- 18314556
- Filed
- May 9, 2023
- Granted
- Oct 20, 2026
- Inventors
- 7
- Claims
- 20
Classified under
G10L 13/10 Physics & computingG10L 13/04 Physics & computingG10L 25/30 Physics & computingG06N 3/044 Physics & computingG10L 13/02 Physics & computingG10L 13/08 Physics & computingMore from Google in Audio & voice
- Google patents voice assistant that cuts off its own answer to hear a new question Sep 15, 2026
- Google patents head-worn device that cleans up voice using bone vibration Sep 17, 2026
- Google patents voice assistant that asks before acting on commands Sep 1, 2026
- Google patents ring design to smooth out microphone sound quality Sep 1, 2026
- Google patents earbud part that combines sound and vibration Sep 8, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.