Netflix patents tech to match video scenes across different languages
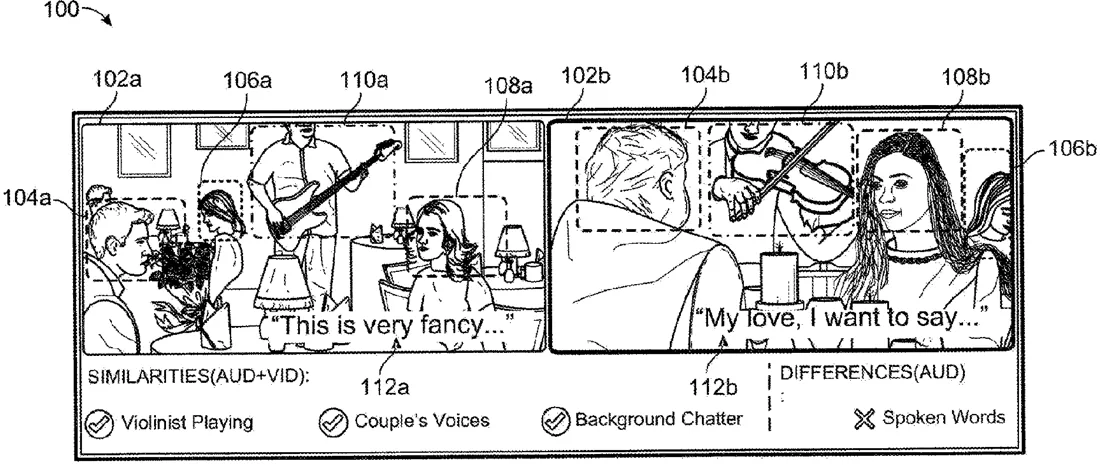
This patent describes a method for training a machine-learning model to recognize video scenes regardless of the language being spoken. It works by feeding the model video clips paired with both the original audio and a dubbed version, teaching it to focus on the visual content and non-speech sounds rather than the specific words.
In the filing’s own words
The disclosed computer-implemented methods and systems include training a machine-learning model to accurately generate representations of similar scenes from long-form videos that have semantically different speech audio. For example, the methods and systems described herein generate machine-learning model training data including video clips and corresponding audio spectrograms. To augment this data, the methods and systems described herein further include dubbed audio spectrograms with the training data such that each video clips corresponds with a primary language audio spectrogram and a secondary language audio spectrogram. By applying a machine-learning model to this training data, the systems and methods described herein teach the machine-learning model to de-emphasize speech audio when generating audio visual representations corresponding to scenes from long-form video. Various other methods, systems, and computer-readable media are also disclosed.
What exactly they claim (claim 1)
1. A computer-implemented method for training a machine-learning model to generate language-invariant video representations, the computer-implemented method comprising: generating a training set comprising, from a long-form video, a video track clip, a primary language audio track corresponding to the video track clip, and a dubbed language audio track corresponding to the video track clip, wherein the dubbed language audio track preserves non-speech audio corresponding to the video track clip and replaces spoken language with translated spoken language; applying, by one or more physical processors, the machine-learning model to the training set to generate: a video representation of the video track clip, a primary-language audio representation of the primary language audio track, and a dubbed-language audio representation of the dubbed language audio track; projecting, by one or more projection heads of the machine-learning model, the video representation, the primary-language audio representation, and the dubbed-language audio representation into a shared representational space; computing, by the one or more physical processors, a contrastive cost between modalities, the contrastive cost comprising a first cost between the projected video representation and the projected primary-language audio representation, and a second cost between the projected video representation and the projected dubbed-language audio representation, wherein the contrastive cost comprises a sum of the first cost and the second cost; and iteratively updating parameters of the machine-learning model based on the contrastive cost over multiple training epochs to train the machine-learning model to position the projected video representation within a threshold distance of each of the projected primary-language audio representation and the projected dubbed-language audio representation within the shared representational space.
Facts
- Company
- Netflix (Netflix, Inc.)
- Official title
- Methods and systems for learning language-invariant audiovisual representations
- Patent number
- US12762858B2
- Application number
- 18505081
- Filed
- Nov 8, 2023
- Granted
- Oct 13, 2026
- Inventors
- 4
- Claims
- 20
Classified under
G06V 20/41 Physics & computingG06V 10/82 Physics & computingMore from Netflix in AI & software
- Netflix patents method to train AI for better video scaling Sep 15, 2026
- Netflix patents method to bundle game frames for smoother streaming Sep 22, 2026
- Netflix patents search system that explains why a show is missing Sep 29, 2026
- Netflix patents method to estimate video depth in real time Sep 24, 2026
- Netflix patents on-device AI to identify objects in streaming video Oct 1, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.