Nvidia patents method to create videos from text using two-step AI
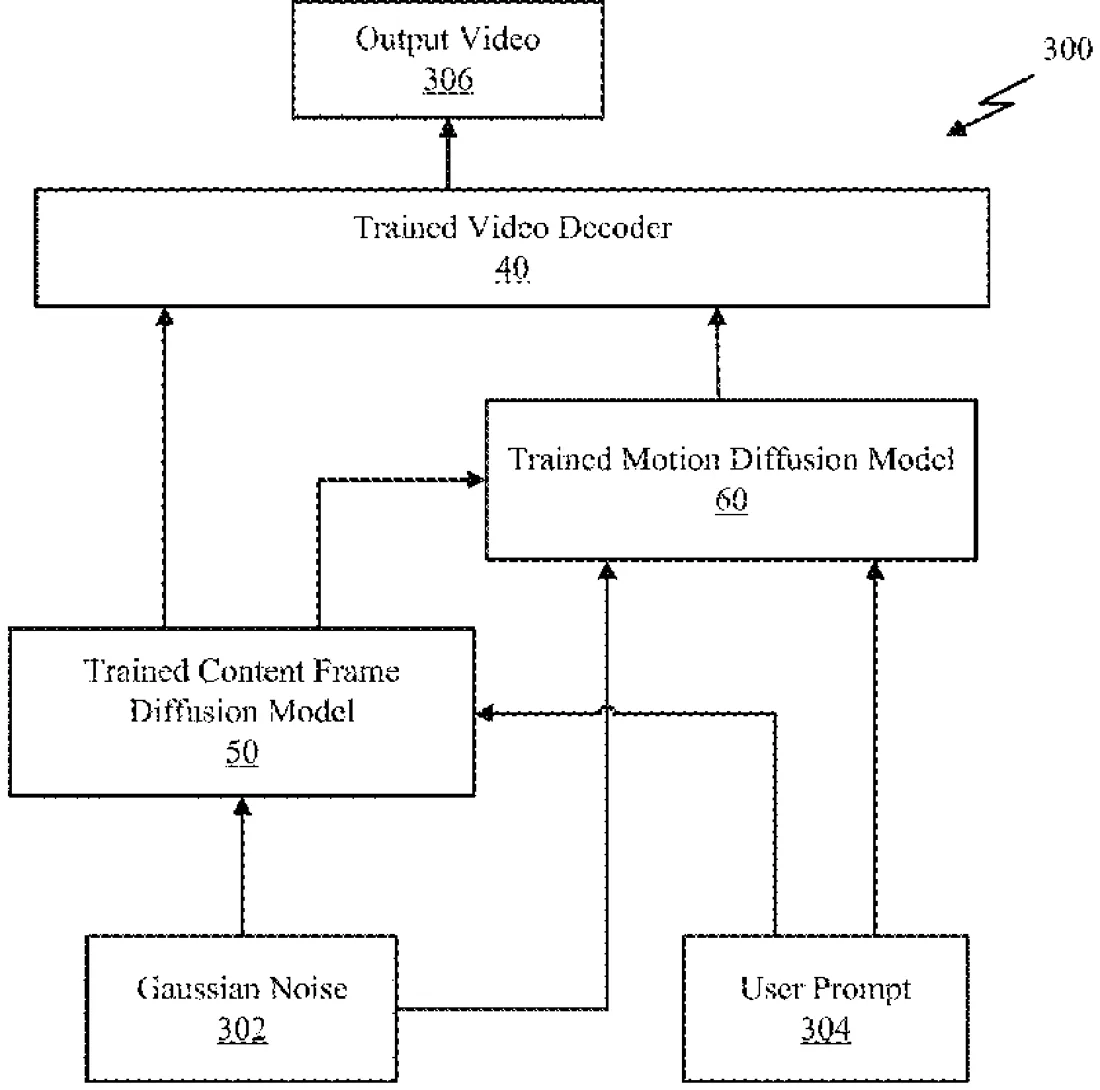
Nvidia describes a system that creates high-resolution videos from text prompts by splitting the process into two parts. It first generates a static image of the scene and then adds movement to that image using a separate, lightweight model.
In the filing’s own words
Systems and methods are disclosed that train a content frame-motion latent diffusion model (CDM) and use the CDM to generate requested videos. The CMD may be a two-stage framework that first compresses videos to a succinct latent space and then learns the video distribution in this latent space. For instance, the CMD may include an autoencoder and two diffusion models. In a first stage, using the autoencoder, a low-dimensional latent decomposition into a content frame and latent motion representation is learned. In the second stage, without adding any new parameters, the content frame distribution may be fine-tuned by using a pretrained image diffusion model, which allows the CMD to leverage the rich visual knowledge in pretrained image diffusion models. In addition, a new lightweight diffusion model may be used to generate motion latent representations that are conditioned on the given content frame.
What exactly they claim (claim 1)
1. A computer-implemented method for using diffusion models to generate a requested video from a user prompt, comprising: inputting the user prompt for the requested video and Gaussian noise into a content frame diffusion model to generate a content frame for the requested video; inputting the generated content frame, the user prompt, and the Gaussian noise into a motion diffusion model to generate motion latent representations corresponding to motions of attributes within the generated content frame that are encoded in a latent space; and generating the requested video based on inputting the generated content frame and the generated motion latent representations into a video decoder.
Facts
- Company
- Nvidia (NVIDIA Corporation)
- Official title
- System and method for efficient text-guided generation of high-resolution videos
- Patent number
- US12749234B2
- Application number
- 18819064
- Filed
- Aug 29, 2024
- Granted
- Sep 29, 2026
- Inventors
- 5
- Claims
- 22
Classified under
G06T 11/00 Physics & computingG06N 3/0455 Physics & computingG06T 9/002 Physics & computingMore from Nvidia in AI & software
- Nvidia patents AI coach that analyzes your gameplay to suggest strategies Oct 13, 2026
- Nvidia patents AI system that writes and voices character conversations Sep 10, 2026
- Nvidia patents system that uses AI to find bugs in game videos Sep 17, 2026
- Nvidia patents AI method to make digital characters move realistically Sep 8, 2026
- Nvidia patents AI system that builds image generators from text prompts Sep 15, 2026
Summaries are simplified from the filing’s own abstract and first claim. A patent filing is not a product announcement.
Patent data and drawings: U.S. Patent and Trademark Office (USPTO). Nebula is not affiliated with or endorsed by the USPTO.